5.0 (#62)
* feat: Add Bioxel asset catalog and layer management functionality

- Introduced a new asset catalog definition file for Blender to manage Bioxel assets.
- Implemented layer caching and snapshot functionality in `layer.py`, allowing for VDB file generation and low-resolution snapshots.
- Created node management functions in `node.py` for handling Bioxel nodes within Blender's Geometry Node Editor.
- Added an operator to extract mesh data from selected nodes in `structure.py`.
- Developed UI panels in `panels.py` for layer management, including import options and layer library display.

* Add unit tests for bioxel module and documentation

- Created README.md for test instructions and categories.
- Implemented comprehensive unit tests for the Data, Layer, and utility functions in the bioxel module.
- Added tests for reading NRRD and DICOM formats, data properties, and edge cases.
- Included tests for real data files to ensure functionality with actual datasets.

* feat: Update .gitattributes and .gitignore for improved asset management and ignore patterns

chore: Add app.json and omoolab.css for Obsidian integration

refactor: Clean up AGENTS.md and remove outdated test files

* feat: Update .gitignore to include scipy_ndimage directory

* feat: Update release workflow and manifest for improved dependency management and layer handling

* feat: Update .gitignore and add binary files for scipy_ndimage across multiple platforms

* feat: Add OPSX commands for archiving, exploring, and proposing changes

* feat: Refactor asset library management and update manifest for improved organization

* feat: Downgrade h5py version to 3.14.0 in requirements and manifest

* feat: Update Help operator and panel labels to use English terminology

* Translate documentation to Chinese, add support format details, and enhance styling with new fonts. Update mkdocs configuration for multilingual support and improve package dependencies.

* feat: Remove default version setting from extra configuration in mkdocs.yml

* fix: Update documentation links to point to the correct URLs for Chinese and English versions

* Add documentation for basic usage, supported formats, and performance tips

- Created English and Chinese documentation for basic usage of the add-on, including data download, import, extraction, and rendering steps.
- Added support format documentation listing compatible file types for the add-on.
- Included links to open databases for volumetric data.
- Provided performance improvement tips for voxel reconstruction and rendering, including settings for low-resolution previews and balanced rendering configurations.

* Add OpenSpec skills for change management and exploration

- Implement openspec-apply-change skill for applying tasks from OpenSpec changes.
- Create openspec-archive-change skill for archiving completed changes.
- Introduce openspec-explore skill for exploring ideas and clarifying requirements.
- Add openspec-propose skill for proposing new changes with generated artifacts.
- Migrate source command skills: source-command-opsx-apply, source-command-opsx-archive, source-command-opsx-explore, and source-command-opsx-propose for improved command handling.

* feat: Update version to 2.0.1, refactor asset library handling, and enhance layer import process

* fix: downgrade scipy version to 1.16.3 in build.py and pyproject.toml

* Remove deprecated modules and functions from bioxel package

- Deleted _ni_support.py, _utils.py, and dtype.py as they contained unused or redundant functions.
- Removed the resize function and related utilities from _warps.py to streamline image processing.
- Cleaned up the skimage module by removing unnecessary imports and functions.

* feat: Add SKIP_MODULE_NAMES to exclude specific modules during import and refactor io_worker import logic

* refactor: Remove known limitations section from documentation for EEVEE NEXT support
This commit is contained in:
 Nan
@@ -1,10 +1,14 @@
|
|||||||
---
|
---
|
||||||
name: "OPSX: Apply"
|
name: "source-command-opsx-apply"
|
||||||
description: Implement tasks from an OpenSpec change (Experimental)
|
description: "Implement tasks from an OpenSpec change (Experimental)"
|
||||||
category: Workflow
|
|
||||||
tags: [workflow, artifacts, experimental]
|
|
||||||
---
|
---
|
||||||
|
|
||||||
|
# source-command-opsx-apply
|
||||||
|
|
||||||
|
Use this skill when the user asks to run the migrated source command `opsx-apply`.
|
||||||
|
|
||||||
|
## Command Template
|
||||||
|
|
||||||
Implement tasks from an OpenSpec change.
|
Implement tasks from an OpenSpec change.
|
||||||
|
|
||||||
**Input**: Optionally specify a change name (e.g., `/opsx:apply add-auth`). If omitted, check if it can be inferred from conversation context. If vague or ambiguous you MUST prompt for available changes.
|
**Input**: Optionally specify a change name (e.g., `/opsx:apply add-auth`). If omitted, check if it can be inferred from conversation context. If vague or ambiguous you MUST prompt for available changes.
|
||||||
@@ -1,10 +1,14 @@
|
|||||||
---
|
---
|
||||||
name: "OPSX: Archive"
|
name: "source-command-opsx-archive"
|
||||||
description: Archive a completed change in the experimental workflow
|
description: "Archive a completed change in the experimental workflow"
|
||||||
category: Workflow
|
|
||||||
tags: [workflow, archive, experimental]
|
|
||||||
---
|
---
|
||||||
|
|
||||||
|
# source-command-opsx-archive
|
||||||
|
|
||||||
|
Use this skill when the user asks to run the migrated source command `opsx-archive`.
|
||||||
|
|
||||||
|
## Command Template
|
||||||
|
|
||||||
Archive a completed change in the experimental workflow.
|
Archive a completed change in the experimental workflow.
|
||||||
|
|
||||||
**Input**: Optionally specify a change name after `/opsx:archive` (e.g., `/opsx:archive add-auth`). If omitted, check if it can be inferred from conversation context. If vague or ambiguous you MUST prompt for available changes.
|
**Input**: Optionally specify a change name after `/opsx:archive` (e.g., `/opsx:archive add-auth`). If omitted, check if it can be inferred from conversation context. If vague or ambiguous you MUST prompt for available changes.
|
||||||
@@ -1,10 +1,14 @@
|
|||||||
---
|
---
|
||||||
name: "OPSX: Explore"
|
name: "source-command-opsx-explore"
|
||||||
description: "Enter explore mode - think through ideas, investigate problems, clarify requirements"
|
description: "Enter explore mode - think through ideas, investigate problems, clarify requirements"
|
||||||
category: Workflow
|
|
||||||
tags: [workflow, explore, experimental, thinking]
|
|
||||||
---
|
---
|
||||||
|
|
||||||
|
# source-command-opsx-explore
|
||||||
|
|
||||||
|
Use this skill when the user asks to run the migrated source command `opsx-explore`.
|
||||||
|
|
||||||
|
## Command Template
|
||||||
|
|
||||||
Enter explore mode. Think deeply. Visualize freely. Follow the conversation wherever it goes.
|
Enter explore mode. Think deeply. Visualize freely. Follow the conversation wherever it goes.
|
||||||
|
|
||||||
**IMPORTANT: Explore mode is for thinking, not implementing.** You may read files, search code, and investigate the codebase, but you must NEVER write code or implement features. If the user asks you to implement something, remind them to exit explore mode first and create a change proposal. You MAY create OpenSpec artifacts (proposals, designs, specs) if the user asks—that's capturing thinking, not implementing.
|
||||||
@@ -1,10 +1,14 @@
|
|||||||
---
|
---
|
||||||
name: "OPSX: Propose"
|
name: "source-command-opsx-propose"
|
||||||
description: Propose a new change - create it and generate all artifacts in one step
|
description: "Propose a new change - create it and generate all artifacts in one step"
|
||||||
category: Workflow
|
|
||||||
tags: [workflow, artifacts, experimental]
|
|
||||||
---
|
---
|
||||||
|
|
||||||
|
# source-command-opsx-propose
|
||||||
|
|
||||||
|
Use this skill when the user asks to run the migrated source command `opsx-propose`.
|
||||||
|
|
||||||
|
## Command Template
|
||||||
|
|
||||||
Propose a new change - create the change and generate all artifacts in one step.
|
Propose a new change - create the change and generate all artifacts in one step.
|
||||||
|
|
||||||
I'll create a change with artifacts:
|
I'll create a change with artifacts:
|
||||||
12
.gitignore
vendored
12
.gitignore
vendored
@@ -1,7 +1,7 @@
|
|||||||
# Tempary files
|
# Tempary files
|
||||||
temp
|
temp
|
||||||
sandbox.*
|
sandbox.*
|
||||||
notes/
|
/notes/
|
||||||
|
|
||||||
# Environments
|
# Environments
|
||||||
.env
|
.env
|
||||||
@@ -22,11 +22,11 @@ secrets/
|
|||||||
SECRETS/
|
SECRETS/
|
||||||
secrets.bak/
|
secrets.bak/
|
||||||
|
|
||||||
# Claude
|
# Claude Code
|
||||||
|
.claude/settings.local.json
|
||||||
.claudian
|
.claudian
|
||||||
|
|
||||||
# Obsidian
|
# Obsidian
|
||||||
|
|
||||||
.obsidian/*
|
.obsidian/*
|
||||||
!.obsidian/snippets
|
!.obsidian/snippets
|
||||||
!.obsidian/app.json
|
!.obsidian/app.json
|
||||||
@@ -389,8 +389,4 @@ dist
|
|||||||
# Vite files
|
# Vite files
|
||||||
vite.config.js.timestamp-*
|
vite.config.js.timestamp-*
|
||||||
vite.config.ts.timestamp-*
|
vite.config.ts.timestamp-*
|
||||||
.vite/
|
.vite/
|
||||||
|
|
||||||
|
|
||||||
# Scipy
|
|
||||||
!scipy_ndimage/*/**
|
|
||||||
@@ -38,11 +38,6 @@ If you want to cite this work, you can cite it from Zenodo:
|
|||||||
|
|
||||||
[](https://zenodo.org/badge/latestdoi/786623459)
|
[](https://zenodo.org/badge/latestdoi/786623459)
|
||||||
|
|
||||||
## Known Limitations
|
|
||||||
|
|
||||||
- Only one cutter supported in EEVEE render
|
|
||||||
- Shader fail to work when convert to mesh.
|
|
||||||
- Section surface cannot be generated when convert to mesh (will be supported soon)
|
|
||||||
|
|
||||||
## Roadmap
|
## Roadmap
|
||||||
|
|
||||||
|
|||||||
11
build.py
11
build.py
@@ -19,7 +19,8 @@ required_packages = ["SimpleITK==2.5.5",
|
|||||||
"transforms3d==0.4.2",
|
"transforms3d==0.4.2",
|
||||||
"tifffile==2024.7.24",
|
"tifffile==2024.7.24",
|
||||||
"matplotlib==3.10.7",
|
"matplotlib==3.10.7",
|
||||||
"pillow==11.2.1"]
|
"pillow==11.2.1",
|
||||||
|
"scipy==1.16.3"]
|
||||||
|
|
||||||
|
|
||||||
platforms = {"windows-x64": Platform(pypi_suffix="win_amd64",
|
platforms = {"windows-x64": Platform(pypi_suffix="win_amd64",
|
||||||
@@ -33,7 +34,8 @@ platforms = {"windows-x64": Platform(pypi_suffix="win_amd64",
|
|||||||
|
|
||||||
packages_to_remove = {
|
packages_to_remove = {
|
||||||
"imagecodecs",
|
"imagecodecs",
|
||||||
"numpy"
|
"numpy",
|
||||||
|
"packaging"
|
||||||
}
|
}
|
||||||
|
|
||||||
|
|
||||||
@@ -45,7 +47,6 @@ def run_python(args: str):
|
|||||||
def build_extension(platform: Platform, python_version: str) -> None:
|
def build_extension(platform: Platform, python_version: str) -> None:
|
||||||
wheel_dirpath = Path("./src/bioxelnodes/wheels")
|
wheel_dirpath = Path("./src/bioxelnodes/wheels")
|
||||||
toml_filepath = Path("./src/bioxelnodes/blender_manifest.toml")
|
toml_filepath = Path("./src/bioxelnodes/blender_manifest.toml")
|
||||||
scipy_ndimage_dirpath = Path("./scipy_ndimage", platform.blender_tag)
|
|
||||||
|
|
||||||
# download required_packages
|
# download required_packages
|
||||||
run_python(
|
run_python(
|
||||||
@@ -62,10 +63,6 @@ def build_extension(platform: Platform, python_version: str) -> None:
|
|||||||
and "universal2" in f.name
|
and "universal2" in f.name
|
||||||
):
|
):
|
||||||
f.rename(Path(f.parent, f.name.replace("universal2", "arm64")))
|
f.rename(Path(f.parent, f.name.replace("universal2", "arm64")))
|
||||||
|
|
||||||
for ndimage_filepath in scipy_ndimage_dirpath.iterdir():
|
|
||||||
to_filepath = Path("./src/bioxelnodes/bioxel/scipy", ndimage_filepath.name)
|
|
||||||
shutil.copy(ndimage_filepath, to_filepath)
|
|
||||||
|
|
||||||
# Load the TOML file
|
# Load the TOML file
|
||||||
with toml_filepath.open("r") as file:
|
with toml_filepath.open("r") as file:
|
||||||
|
|||||||
@@ -49,15 +49,8 @@ Welcome to our [discord server](https://discord.gg/pYkNyq2TjE), if you have any
|
|||||||
|
|
||||||
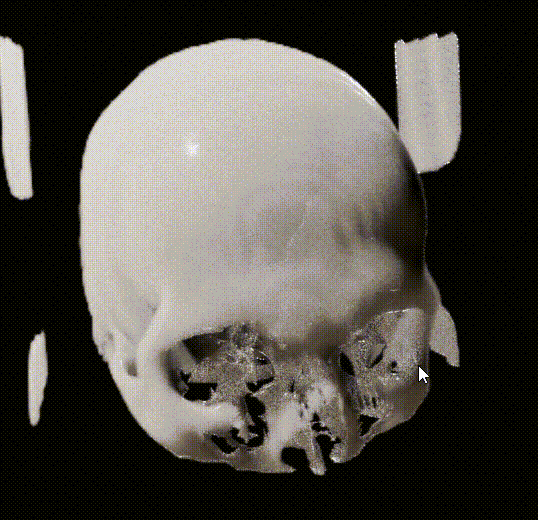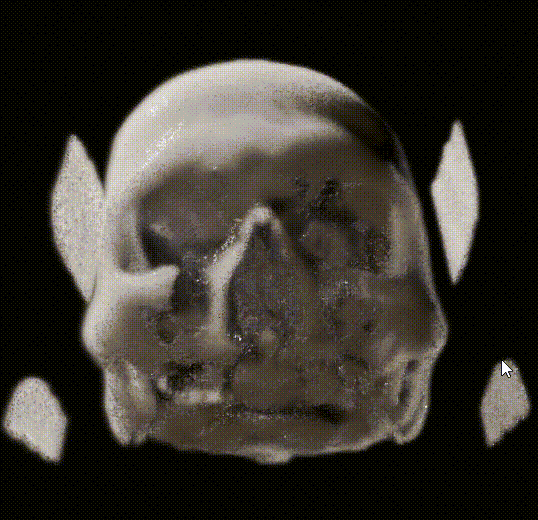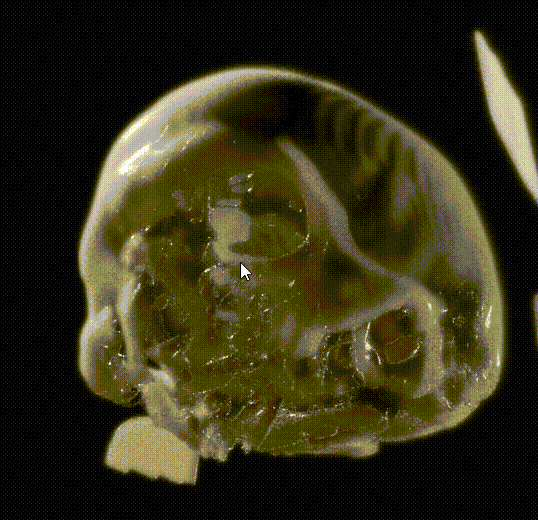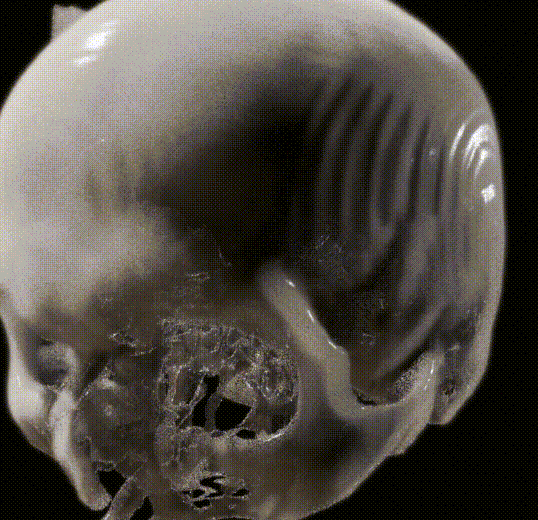
|

|
||||||
|
|
||||||
👍 EEVEE NEXT is absolutely AWESOME! Bioxel Nodes is fully support EEVEE NEXT now! However, there are some limitations:
|
👍 EEVEE NEXT is absolutely AWESOME! Bioxel Nodes is fully support EEVEE NEXT now!
|
||||||
|
|
||||||
1. Only one cutter supported.
|
|
||||||
2. EEVEE result is not that great as Cycles does.
|
|
||||||
|
|
||||||
## Known Limitations
|
|
||||||
|
|
||||||
- Only works with Cycles CPU , Cycles GPU (OptiX), EEVEE
|
|
||||||
- Section surface cannot be generated when convert to mesh (will be supported soon)
|
|
||||||
|
|
||||||
## Roadmap
|
## Roadmap
|
||||||
|
|
||||||
|
|||||||
@@ -49,15 +49,7 @@ Bioxel Nodes 是一款用于科学体数据可视化的 Blender 插件。它利
|
|||||||
|
|
||||||

|

|
||||||
|
|
||||||
EEVEE NEXT 太棒了!Bioxel Nodes 现在全面支持 EEVEE NEXT!但仍有以下限制:
|
EEVEE NEXT 太棒了!Bioxel Nodes 现在全面支持 EEVEE NEXT!
|
||||||
|
|
||||||
1. 仅支持一个切割器
|
|
||||||
2. EEVEE 渲染效果不如 Cycles
|
|
||||||
|
|
||||||
## 已知限制
|
|
||||||
|
|
||||||
- 仅支持 Cycles CPU、Cycles GPU (OptiX)、EEVEE
|
|
||||||
- 转换为网格时无法生成剖面(即将支持)
|
|
||||||
|
|
||||||
## 路线图
|
## 路线图
|
||||||
|
|
||||||
|
|||||||
@@ -1,8 +1,8 @@
|
|||||||
[project]
|
[project]
|
||||||
name = "bioxelnodes"
|
name = "bioxelnodes"
|
||||||
version = "1.0.9"
|
version = "2.0.1"
|
||||||
description = ""
|
description = ""
|
||||||
authors = [{ name = "Ma Nan", email = "icrdr2010@outlook.com" }]
|
authors = [{ name = "MaNan", email = "icrdr2010@outlook.com" }]
|
||||||
requires-python = ">=3.11.0,<3.12.dev0"
|
requires-python = ">=3.11.0,<3.12.dev0"
|
||||||
readme = "README.md"
|
readme = "README.md"
|
||||||
license = "MIT"
|
license = "MIT"
|
||||||
@@ -13,6 +13,7 @@ dependencies = [
|
|||||||
"h5py==3.11.0",
|
"h5py==3.11.0",
|
||||||
"transforms3d==0.4.2",
|
"transforms3d==0.4.2",
|
||||||
"matplotlib==3.10.7",
|
"matplotlib==3.10.7",
|
||||||
|
"scipy==1.16.3",
|
||||||
]
|
]
|
||||||
|
|
||||||
[dependency-groups]
|
[dependency-groups]
|
||||||
|
|||||||
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
@@ -1,7 +1,7 @@
|
|||||||
import bpy
|
import bpy
|
||||||
import bpy.utils.previews as previews
|
import bpy.utils.previews as previews
|
||||||
|
|
||||||
from .constants import NODE_LIB_DIRPATH, PREVIEW_COLLECTIONS
|
from .constants import PREVIEW_COLLECTIONS
|
||||||
from .props import _bioxel_layer_items, _update_layer_gallery, _update_snapshot_z
|
from .props import _bioxel_layer_items, _update_layer_gallery, _update_snapshot_z
|
||||||
|
|
||||||
from . import auto_load
|
from . import auto_load
|
||||||
@@ -10,37 +10,6 @@ from . import menus
|
|||||||
auto_load.init()
|
auto_load.init()
|
||||||
|
|
||||||
|
|
||||||
def add_asset_library():
|
|
||||||
"""Add Bioxel asset library, ensuring only one exists by removing duplicates first."""
|
|
||||||
if not NODE_LIB_DIRPATH.exists():
|
|
||||||
print(f"Node library path does not exist - {NODE_LIB_DIRPATH}")
|
|
||||||
return
|
|
||||||
|
|
||||||
lib_path_str = str(NODE_LIB_DIRPATH)
|
|
||||||
prefs = bpy.context.preferences.filepaths.asset_libraries
|
|
||||||
|
|
||||||
# Add new library
|
|
||||||
new_lib = prefs.new()
|
|
||||||
new_lib.name = "O Bioxel"
|
|
||||||
new_lib.path = lib_path_str
|
|
||||||
new_lib.import_method = "PACK"
|
|
||||||
|
|
||||||
print(f"Add Bioxel Nodes library: {lib_path_str}")
|
|
||||||
|
|
||||||
|
|
||||||
def remove_asset_library_if_exists():
|
|
||||||
"""Remove the Bioxel asset library entry if it was added (by path or name)."""
|
|
||||||
lib_path_str = str(NODE_LIB_DIRPATH)
|
|
||||||
prefs = bpy.context.preferences.filepaths.asset_libraries
|
|
||||||
|
|
||||||
for lib in list(prefs):
|
|
||||||
try:
|
|
||||||
if "Bioxel" in lib.name or lib.path == lib_path_str:
|
|
||||||
prefs.remove(lib)
|
|
||||||
except Exception:
|
|
||||||
continue
|
|
||||||
|
|
||||||
|
|
||||||
def register():
|
def register():
|
||||||
pcoll = previews.new()
|
pcoll = previews.new()
|
||||||
pcoll.layer_previews = ()
|
pcoll.layer_previews = ()
|
||||||
@@ -72,12 +41,9 @@ def register():
|
|||||||
|
|
||||||
auto_load.register()
|
auto_load.register()
|
||||||
menus.add()
|
menus.add()
|
||||||
remove_asset_library_if_exists()
|
|
||||||
add_asset_library()
|
|
||||||
|
|
||||||
|
|
||||||
def unregister():
|
def unregister():
|
||||||
remove_asset_library_if_exists()
|
|
||||||
menus.remove()
|
menus.remove()
|
||||||
auto_load.unregister()
|
auto_load.unregister()
|
||||||
|
|
||||||
|
|||||||
73
src/bioxelnodes/asset_library.py
Normal file
73
src/bioxelnodes/asset_library.py
Normal file
@@ -0,0 +1,73 @@
|
|||||||
|
import bpy
|
||||||
|
from pathlib import Path
|
||||||
|
|
||||||
|
from .constants import NODE_LIB_DIRPATH
|
||||||
|
|
||||||
|
|
||||||
|
ASSET_LIBRARY_NAME = "O Bioxel"
|
||||||
|
|
||||||
|
|
||||||
|
def _asset_library_path():
|
||||||
|
return str(NODE_LIB_DIRPATH)
|
||||||
|
|
||||||
|
|
||||||
|
def _normalized_path(path):
|
||||||
|
return Path(bpy.path.abspath(path)).resolve()
|
||||||
|
|
||||||
|
|
||||||
|
def _asset_libraries():
|
||||||
|
return bpy.context.preferences.filepaths.asset_libraries
|
||||||
|
|
||||||
|
|
||||||
|
def get_bioxel_asset_library():
|
||||||
|
lib_path = _normalized_path(_asset_library_path())
|
||||||
|
|
||||||
|
for lib in _asset_libraries():
|
||||||
|
try:
|
||||||
|
if _normalized_path(lib.path) == lib_path:
|
||||||
|
return lib
|
||||||
|
except Exception:
|
||||||
|
continue
|
||||||
|
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def has_bioxel_asset_library():
|
||||||
|
return get_bioxel_asset_library() is not None
|
||||||
|
|
||||||
|
|
||||||
|
def add_bioxel_asset_library():
|
||||||
|
if not NODE_LIB_DIRPATH.exists():
|
||||||
|
raise FileNotFoundError(f"Node library path does not exist: {NODE_LIB_DIRPATH}")
|
||||||
|
|
||||||
|
prefs = _asset_libraries()
|
||||||
|
lib = get_bioxel_asset_library()
|
||||||
|
|
||||||
|
if lib is None:
|
||||||
|
for item in prefs:
|
||||||
|
try:
|
||||||
|
if item.name == ASSET_LIBRARY_NAME:
|
||||||
|
lib = item
|
||||||
|
break
|
||||||
|
except Exception:
|
||||||
|
continue
|
||||||
|
|
||||||
|
if lib is None:
|
||||||
|
lib = prefs.new()
|
||||||
|
|
||||||
|
lib.name = ASSET_LIBRARY_NAME
|
||||||
|
lib.path = _asset_library_path()
|
||||||
|
lib.import_method = "PACK"
|
||||||
|
return lib
|
||||||
|
|
||||||
|
|
||||||
|
def remove_bioxel_asset_library_if_exists():
|
||||||
|
lib_path = _normalized_path(_asset_library_path())
|
||||||
|
prefs = _asset_libraries()
|
||||||
|
|
||||||
|
for lib in list(prefs):
|
||||||
|
try:
|
||||||
|
if "Bioxel" in lib.name or _normalized_path(lib.path) == lib_path:
|
||||||
|
prefs.remove(lib)
|
||||||
|
except Exception:
|
||||||
|
continue
|
||||||
Binary file not shown.
@@ -15,6 +15,9 @@ blender_version = bpy.app.version
|
|||||||
|
|
||||||
modules = None
|
modules = None
|
||||||
ordered_classes = None
|
ordered_classes = None
|
||||||
|
SKIP_MODULE_NAMES = {
|
||||||
|
"operators.io_worker",
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
def init():
|
def init():
|
||||||
@@ -57,6 +60,8 @@ def get_all_submodules(directory):
|
|||||||
|
|
||||||
def iter_submodules(path, package_name):
|
def iter_submodules(path, package_name):
|
||||||
for name in sorted(iter_submodule_names(path)):
|
for name in sorted(iter_submodule_names(path)):
|
||||||
|
if name in SKIP_MODULE_NAMES:
|
||||||
|
continue
|
||||||
yield importlib.import_module("." + name, package_name)
|
yield importlib.import_module("." + name, package_name)
|
||||||
|
|
||||||
|
|
||||||
|
|||||||
@@ -7,8 +7,7 @@ try:
|
|||||||
except ImportError:
|
except ImportError:
|
||||||
vdb = None
|
vdb = None
|
||||||
|
|
||||||
from . import scipy
|
from scipy import ndimage as ndi
|
||||||
from . import scipy as ndi
|
|
||||||
|
|
||||||
# 3rd-party
|
# 3rd-party
|
||||||
import transforms3d
|
import transforms3d
|
||||||
@@ -83,21 +82,17 @@ class Layer():
|
|||||||
for f in range(self.frame_count):
|
for f in range(self.frame_count):
|
||||||
mask_frame = mask[f, :, :, :]
|
mask_frame = mask[f, :, :, :]
|
||||||
if smooth > 0:
|
if smooth > 0:
|
||||||
mask_frame = scipy.median_filter(mask_frame.astype(np.float32),
|
mask_frame = ndi.median_filter(mask_frame.astype(np.float32),
|
||||||
mode="nearest",
|
mode="nearest",
|
||||||
size=smooth)
|
size=smooth)
|
||||||
# mask_frame = scipy.median_filter(
|
|
||||||
# mask_frame.astype(np.float32), size=2)
|
|
||||||
mask_frames += (mask_frame,)
|
mask_frames += (mask_frame,)
|
||||||
elif mask.ndim == 3:
|
elif mask.ndim == 3:
|
||||||
for f in range(self.frame_count):
|
for f in range(self.frame_count):
|
||||||
mask_frame = mask[:, :, :]
|
mask_frame = mask[:, :, :]
|
||||||
if smooth > 0:
|
if smooth > 0:
|
||||||
mask_frame = scipy.median_filter(mask_frame.astype(np.float32),
|
mask_frame = ndi.median_filter(mask_frame.astype(np.float32),
|
||||||
mode="nearest",
|
mode="nearest",
|
||||||
size=smooth)
|
size=smooth)
|
||||||
# mask_frame = scipy.median_filter(
|
|
||||||
# mask_frame.astype(np.float32), size=2)
|
|
||||||
mask_frames += (mask_frame,)
|
mask_frames += (mask_frame,)
|
||||||
else:
|
else:
|
||||||
raise Exception("Mask shape order should be TXYZ or XYZ")
|
raise Exception("Mask shape order should be TXYZ or XYZ")
|
||||||
@@ -127,9 +122,9 @@ class Layer():
|
|||||||
|
|
||||||
frame = data[f, :, :, :, :]
|
frame = data[f, :, :, :, :]
|
||||||
if smooth > 0:
|
if smooth > 0:
|
||||||
frame = scipy.median_filter(frame.astype(np.float32),
|
frame = ndi.median_filter(frame.astype(np.float32),
|
||||||
mode="nearest",
|
mode="nearest",
|
||||||
size=smooth)
|
size=smooth)
|
||||||
|
|
||||||
factors = np.divide(self.shape, shape)
|
factors = np.divide(self.shape, shape)
|
||||||
zoom_factors = [1 / f for f in factors]
|
zoom_factors = [1 / f for f in factors]
|
||||||
|
|||||||
@@ -1,5 +0,0 @@
|
|||||||
from ._interpolation import zoom
|
|
||||||
from ._filters import (gaussian_filter,
|
|
||||||
median_filter,
|
|
||||||
maximum_filter,
|
|
||||||
minimum_filter)
|
|
||||||
File diff suppressed because it is too large
Load Diff
@@ -1,314 +0,0 @@
|
|||||||
import numpy as np
|
|
||||||
import warnings
|
|
||||||
|
|
||||||
from . import _ni_support
|
|
||||||
from . import _nd_image
|
|
||||||
from ._utils import normalize_axis_index
|
|
||||||
|
|
||||||
|
|
||||||
def _prepad_for_spline_filter(input, mode, cval):
|
|
||||||
if mode in ['nearest', 'grid-constant']:
|
|
||||||
npad = 12
|
|
||||||
if mode == 'grid-constant':
|
|
||||||
padded = np.pad(input, npad, mode='constant',
|
|
||||||
constant_values=cval)
|
|
||||||
elif mode == 'nearest':
|
|
||||||
padded = np.pad(input, npad, mode='edge')
|
|
||||||
else:
|
|
||||||
# other modes have exact boundary conditions implemented so
|
|
||||||
# no prepadding is needed
|
|
||||||
npad = 0
|
|
||||||
padded = input
|
|
||||||
return padded, npad
|
|
||||||
|
|
||||||
|
|
||||||
def spline_filter1d(input, order=3, axis=-1, output=np.float64,
|
|
||||||
mode='mirror'):
|
|
||||||
"""
|
|
||||||
Calculate a 1-D spline filter along the given axis.
|
|
||||||
|
|
||||||
The lines of the array along the given axis are filtered by a
|
|
||||||
spline filter. The order of the spline must be >= 2 and <= 5.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
%(input)s
|
|
||||||
order : int, optional
|
|
||||||
The order of the spline, default is 3.
|
|
||||||
axis : int, optional
|
|
||||||
The axis along which the spline filter is applied. Default is the last
|
|
||||||
axis.
|
|
||||||
output : ndarray or dtype, optional
|
|
||||||
The array in which to place the output, or the dtype of the returned
|
|
||||||
array. Default is ``numpy.float64``.
|
|
||||||
%(mode_interp_mirror)s
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
spline_filter1d : ndarray
|
|
||||||
The filtered input.
|
|
||||||
|
|
||||||
See Also
|
|
||||||
--------
|
|
||||||
spline_filter : Multidimensional spline filter.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
All of the interpolation functions in `ndimage` do spline interpolation of
|
|
||||||
the input image. If using B-splines of `order > 1`, the input image
|
|
||||||
values have to be converted to B-spline coefficients first, which is
|
|
||||||
done by applying this 1-D filter sequentially along all
|
|
||||||
axes of the input. All functions that require B-spline coefficients
|
|
||||||
will automatically filter their inputs, a behavior controllable with
|
|
||||||
the `prefilter` keyword argument. For functions that accept a `mode`
|
|
||||||
parameter, the result will only be correct if it matches the `mode`
|
|
||||||
used when filtering.
|
|
||||||
|
|
||||||
For complex-valued `input`, this function processes the real and imaginary
|
|
||||||
components independently.
|
|
||||||
|
|
||||||
.. versionadded:: 1.6.0
|
|
||||||
Complex-valued support added.
|
|
||||||
|
|
||||||
Examples
|
|
||||||
--------
|
|
||||||
We can filter an image using 1-D spline along the given axis:
|
|
||||||
|
|
||||||
>>> from scipy.ndimage import spline_filter1d
|
|
||||||
>>> import numpy as np
|
|
||||||
>>> import matplotlib.pyplot as plt
|
|
||||||
>>> orig_img = np.eye(20) # create an image
|
|
||||||
>>> orig_img[10, :] = 1.0
|
|
||||||
>>> sp_filter_axis_0 = spline_filter1d(orig_img, axis=0)
|
|
||||||
>>> sp_filter_axis_1 = spline_filter1d(orig_img, axis=1)
|
|
||||||
>>> f, ax = plt.subplots(1, 3, sharex=True)
|
|
||||||
>>> for ind, data in enumerate([[orig_img, "original image"],
|
|
||||||
... [sp_filter_axis_0, "spline filter (axis=0)"],
|
|
||||||
... [sp_filter_axis_1, "spline filter (axis=1)"]]):
|
|
||||||
... ax[ind].imshow(data[0], cmap='gray_r')
|
|
||||||
... ax[ind].set_title(data[1])
|
|
||||||
>>> plt.tight_layout()
|
|
||||||
>>> plt.show()
|
|
||||||
|
|
||||||
"""
|
|
||||||
if order < 0 or order > 5:
|
|
||||||
raise RuntimeError('spline order not supported')
|
|
||||||
input = np.asarray(input)
|
|
||||||
complex_output = np.iscomplexobj(input)
|
|
||||||
output = _ni_support._get_output(output, input,
|
|
||||||
complex_output=complex_output)
|
|
||||||
if complex_output:
|
|
||||||
spline_filter1d(input.real, order, axis, output.real, mode)
|
|
||||||
spline_filter1d(input.imag, order, axis, output.imag, mode)
|
|
||||||
return output
|
|
||||||
if order in [0, 1]:
|
|
||||||
output[...] = np.array(input)
|
|
||||||
else:
|
|
||||||
mode = _ni_support._extend_mode_to_code(mode)
|
|
||||||
axis = normalize_axis_index(axis, input.ndim)
|
|
||||||
_nd_image.spline_filter1d(input, order, axis, output, mode)
|
|
||||||
return output
|
|
||||||
|
|
||||||
|
|
||||||
def spline_filter(input, order=3, output=np.float64, mode='mirror'):
|
|
||||||
"""
|
|
||||||
Multidimensional spline filter.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
%(input)s
|
|
||||||
order : int, optional
|
|
||||||
The order of the spline, default is 3.
|
|
||||||
output : ndarray or dtype, optional
|
|
||||||
The array in which to place the output, or the dtype of the returned
|
|
||||||
array. Default is ``numpy.float64``.
|
|
||||||
%(mode_interp_mirror)s
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
spline_filter : ndarray
|
|
||||||
Filtered array. Has the same shape as `input`.
|
|
||||||
|
|
||||||
See Also
|
|
||||||
--------
|
|
||||||
spline_filter1d : Calculate a 1-D spline filter along the given axis.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The multidimensional filter is implemented as a sequence of
|
|
||||||
1-D spline filters. The intermediate arrays are stored
|
|
||||||
in the same data type as the output. Therefore, for output types
|
|
||||||
with a limited precision, the results may be imprecise because
|
|
||||||
intermediate results may be stored with insufficient precision.
|
|
||||||
|
|
||||||
For complex-valued `input`, this function processes the real and imaginary
|
|
||||||
components independently.
|
|
||||||
|
|
||||||
.. versionadded:: 1.6.0
|
|
||||||
Complex-valued support added.
|
|
||||||
|
|
||||||
Examples
|
|
||||||
--------
|
|
||||||
We can filter an image using multidimentional splines:
|
|
||||||
|
|
||||||
>>> from scipy.ndimage import spline_filter
|
|
||||||
>>> import numpy as np
|
|
||||||
>>> import matplotlib.pyplot as plt
|
|
||||||
>>> orig_img = np.eye(20) # create an image
|
|
||||||
>>> orig_img[10, :] = 1.0
|
|
||||||
>>> sp_filter = spline_filter(orig_img, order=3)
|
|
||||||
>>> f, ax = plt.subplots(1, 2, sharex=True)
|
|
||||||
>>> for ind, data in enumerate([[orig_img, "original image"],
|
|
||||||
... [sp_filter, "spline filter"]]):
|
|
||||||
... ax[ind].imshow(data[0], cmap='gray_r')
|
|
||||||
... ax[ind].set_title(data[1])
|
|
||||||
>>> plt.tight_layout()
|
|
||||||
>>> plt.show()
|
|
||||||
|
|
||||||
"""
|
|
||||||
if order < 2 or order > 5:
|
|
||||||
raise RuntimeError('spline order not supported')
|
|
||||||
input = np.asarray(input)
|
|
||||||
complex_output = np.iscomplexobj(input)
|
|
||||||
output = _ni_support._get_output(output, input,
|
|
||||||
complex_output=complex_output)
|
|
||||||
if complex_output:
|
|
||||||
spline_filter(input.real, order, output.real, mode)
|
|
||||||
spline_filter(input.imag, order, output.imag, mode)
|
|
||||||
return output
|
|
||||||
if order not in [0, 1] and input.ndim > 0:
|
|
||||||
for axis in range(input.ndim):
|
|
||||||
spline_filter1d(input, order, axis, output=output, mode=mode)
|
|
||||||
input = output
|
|
||||||
else:
|
|
||||||
output[...] = input[...]
|
|
||||||
return output
|
|
||||||
|
|
||||||
|
|
||||||
def zoom(input, zoom, output=None, order=3, mode='constant', cval=0.0,
|
|
||||||
prefilter=True, *, grid_mode=False):
|
|
||||||
"""
|
|
||||||
Zoom an array.
|
|
||||||
|
|
||||||
The array is zoomed using spline interpolation of the requested order.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
%(input)s
|
|
||||||
zoom : float or sequence
|
|
||||||
The zoom factor along the axes. If a float, `zoom` is the same for each
|
|
||||||
axis. If a sequence, `zoom` should contain one value for each axis.
|
|
||||||
%(output)s
|
|
||||||
order : int, optional
|
|
||||||
The order of the spline interpolation, default is 3.
|
|
||||||
The order has to be in the range 0-5.
|
|
||||||
%(mode_interp_constant)s
|
|
||||||
%(cval)s
|
|
||||||
%(prefilter)s
|
|
||||||
grid_mode : bool, optional
|
|
||||||
If False, the distance from the pixel centers is zoomed. Otherwise, the
|
|
||||||
distance including the full pixel extent is used. For example, a 1d
|
|
||||||
signal of length 5 is considered to have length 4 when `grid_mode` is
|
|
||||||
False, but length 5 when `grid_mode` is True. See the following
|
|
||||||
visual illustration:
|
|
||||||
|
|
||||||
.. code-block:: text
|
|
||||||
|
|
||||||
| pixel 1 | pixel 2 | pixel 3 | pixel 4 | pixel 5 |
|
|
||||||
|<-------------------------------------->|
|
|
||||||
vs.
|
|
||||||
|<----------------------------------------------->|
|
|
||||||
|
|
||||||
The starting point of the arrow in the diagram above corresponds to
|
|
||||||
coordinate location 0 in each mode.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
zoom : ndarray
|
|
||||||
The zoomed input.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
For complex-valued `input`, this function zooms the real and imaginary
|
|
||||||
components independently.
|
|
||||||
|
|
||||||
.. versionadded:: 1.6.0
|
|
||||||
Complex-valued support added.
|
|
||||||
|
|
||||||
Examples
|
|
||||||
--------
|
|
||||||
>>> from scipy import ndimage, datasets
|
|
||||||
>>> import matplotlib.pyplot as plt
|
|
||||||
|
|
||||||
>>> fig = plt.figure()
|
|
||||||
>>> ax1 = fig.add_subplot(121) # left side
|
|
||||||
>>> ax2 = fig.add_subplot(122) # right side
|
|
||||||
>>> ascent = datasets.ascent()
|
|
||||||
>>> result = ndimage.zoom(ascent, 3.0)
|
|
||||||
>>> ax1.imshow(ascent, vmin=0, vmax=255)
|
|
||||||
>>> ax2.imshow(result, vmin=0, vmax=255)
|
|
||||||
>>> plt.show()
|
|
||||||
|
|
||||||
>>> print(ascent.shape)
|
|
||||||
(512, 512)
|
|
||||||
|
|
||||||
>>> print(result.shape)
|
|
||||||
(1536, 1536)
|
|
||||||
"""
|
|
||||||
if order < 0 or order > 5:
|
|
||||||
raise RuntimeError('spline order not supported')
|
|
||||||
input = np.asarray(input)
|
|
||||||
if input.ndim < 1:
|
|
||||||
raise RuntimeError('input and output rank must be > 0')
|
|
||||||
zoom = _ni_support._normalize_sequence(zoom, input.ndim)
|
|
||||||
output_shape = tuple(
|
|
||||||
[int(round(ii * jj)) for ii, jj in zip(input.shape, zoom)])
|
|
||||||
complex_output = np.iscomplexobj(input)
|
|
||||||
output = _ni_support._get_output(output, input, shape=output_shape,
|
|
||||||
complex_output=complex_output)
|
|
||||||
if complex_output:
|
|
||||||
# import under different name to avoid confusion with zoom parameter
|
|
||||||
from scipy.ndimage._interpolation import zoom as _zoom
|
|
||||||
|
|
||||||
kwargs = dict(order=order, mode=mode, prefilter=prefilter)
|
|
||||||
_zoom(input.real, zoom, output=output.real,
|
|
||||||
cval=np.real(cval), **kwargs)
|
|
||||||
_zoom(input.imag, zoom, output=output.imag,
|
|
||||||
cval=np.imag(cval), **kwargs)
|
|
||||||
return output
|
|
||||||
if prefilter and order > 1:
|
|
||||||
padded, npad = _prepad_for_spline_filter(input, mode, cval)
|
|
||||||
filtered = spline_filter(padded, order, output=np.float64, mode=mode)
|
|
||||||
else:
|
|
||||||
npad = 0
|
|
||||||
filtered = input
|
|
||||||
if grid_mode:
|
|
||||||
# warn about modes that may have surprising behavior
|
|
||||||
suggest_mode = None
|
|
||||||
if mode == 'constant':
|
|
||||||
suggest_mode = 'grid-constant'
|
|
||||||
elif mode == 'wrap':
|
|
||||||
suggest_mode = 'grid-wrap'
|
|
||||||
if suggest_mode is not None:
|
|
||||||
warnings.warn(
|
|
||||||
(f"It is recommended to use mode = {suggest_mode} instead of {mode} "
|
|
||||||
f"when grid_mode is True."),
|
|
||||||
stacklevel=2
|
|
||||||
)
|
|
||||||
mode = _ni_support._extend_mode_to_code(mode)
|
|
||||||
|
|
||||||
zoom_div = np.array(output_shape)
|
|
||||||
zoom_nominator = np.array(input.shape)
|
|
||||||
if not grid_mode:
|
|
||||||
zoom_div -= 1
|
|
||||||
zoom_nominator -= 1
|
|
||||||
|
|
||||||
# Zooming to infinite values is unpredictable, so just choose
|
|
||||||
# zoom factor 1 instead
|
|
||||||
zoom = np.divide(zoom_nominator, zoom_div,
|
|
||||||
out=np.ones_like(input.shape, dtype=np.float64),
|
|
||||||
where=zoom_div != 0)
|
|
||||||
zoom = np.ascontiguousarray(zoom)
|
|
||||||
_nd_image.zoom_shift(filtered, zoom, None, output, order, mode, cval, npad,
|
|
||||||
grid_mode)
|
|
||||||
return output
|
|
||||||
@@ -1,120 +0,0 @@
|
|||||||
# Copyright (C) 2003-2005 Peter J. Verveer
|
|
||||||
#
|
|
||||||
# Redistribution and use in source and binary forms, with or without
|
|
||||||
# modification, are permitted provided that the following conditions
|
|
||||||
# are met:
|
|
||||||
#
|
|
||||||
# 1. Redistributions of source code must retain the above copyright
|
|
||||||
# notice, this list of conditions and the following disclaimer.
|
|
||||||
#
|
|
||||||
# 2. Redistributions in binary form must reproduce the above
|
|
||||||
# copyright notice, this list of conditions and the following
|
|
||||||
# disclaimer in the documentation and/or other materials provided
|
|
||||||
# with the distribution.
|
|
||||||
#
|
|
||||||
# 3. The name of the author may not be used to endorse or promote
|
|
||||||
# products derived from this software without specific prior
|
|
||||||
# written permission.
|
|
||||||
#
|
|
||||||
# THIS SOFTWARE IS PROVIDED BY THE AUTHOR ``AS IS'' AND ANY EXPRESS
|
|
||||||
# OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED
|
|
||||||
# WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE
|
|
||||||
# ARE DISCLAIMED. IN NO EVENT SHALL THE AUTHOR BE LIABLE FOR ANY
|
|
||||||
# DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
|
|
||||||
# DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE
|
|
||||||
# GOODS OR SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS
|
|
||||||
# INTERRUPTION) HOWEVER CAUSED AND ON ANY THEORY OF LIABILITY,
|
|
||||||
# WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT (INCLUDING
|
|
||||||
# NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE OF THIS
|
|
||||||
# SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
|
||||||
|
|
||||||
from collections.abc import Iterable
|
|
||||||
import operator
|
|
||||||
import warnings
|
|
||||||
import numpy as np
|
|
||||||
|
|
||||||
|
|
||||||
def _extend_mode_to_code(mode):
|
|
||||||
"""Convert an extension mode to the corresponding integer code.
|
|
||||||
"""
|
|
||||||
if mode == 'nearest':
|
|
||||||
return 0
|
|
||||||
elif mode == 'wrap':
|
|
||||||
return 1
|
|
||||||
elif mode in ['reflect', 'grid-mirror']:
|
|
||||||
return 2
|
|
||||||
elif mode == 'mirror':
|
|
||||||
return 3
|
|
||||||
elif mode == 'constant':
|
|
||||||
return 4
|
|
||||||
elif mode == 'grid-wrap':
|
|
||||||
return 5
|
|
||||||
elif mode == 'grid-constant':
|
|
||||||
return 6
|
|
||||||
else:
|
|
||||||
raise RuntimeError('boundary mode not supported')
|
|
||||||
|
|
||||||
|
|
||||||
def _normalize_sequence(input, rank):
|
|
||||||
"""If input is a scalar, create a sequence of length equal to the
|
|
||||||
rank by duplicating the input. If input is a sequence,
|
|
||||||
check if its length is equal to the length of array.
|
|
||||||
"""
|
|
||||||
is_str = isinstance(input, str)
|
|
||||||
if not is_str and isinstance(input, Iterable):
|
|
||||||
normalized = list(input)
|
|
||||||
if len(normalized) != rank:
|
|
||||||
err = "sequence argument must have length equal to input rank"
|
|
||||||
raise RuntimeError(err)
|
|
||||||
else:
|
|
||||||
normalized = [input] * rank
|
|
||||||
return normalized
|
|
||||||
|
|
||||||
|
|
||||||
def _get_output(output, input, shape=None, complex_output=False):
|
|
||||||
if shape is None:
|
|
||||||
shape = input.shape
|
|
||||||
if output is None:
|
|
||||||
if not complex_output:
|
|
||||||
output = np.zeros(shape, dtype=input.dtype.name)
|
|
||||||
else:
|
|
||||||
complex_type = np.promote_types(input.dtype, np.complex64)
|
|
||||||
output = np.zeros(shape, dtype=complex_type)
|
|
||||||
elif isinstance(output, (type, np.dtype)):
|
|
||||||
# Classes (like `np.float32`) and dtypes are interpreted as dtype
|
|
||||||
if complex_output and np.dtype(output).kind != 'c':
|
|
||||||
warnings.warn(
|
|
||||||
"promoting specified output dtype to complex", stacklevel=3)
|
|
||||||
output = np.promote_types(output, np.complex64)
|
|
||||||
output = np.zeros(shape, dtype=output)
|
|
||||||
elif isinstance(output, str):
|
|
||||||
output = np.dtype(output)
|
|
||||||
if complex_output and output.kind != 'c':
|
|
||||||
raise RuntimeError("output must have complex dtype")
|
|
||||||
elif not issubclass(output.type, np.number):
|
|
||||||
raise RuntimeError("output must have numeric dtype")
|
|
||||||
output = np.zeros(shape, dtype=output)
|
|
||||||
elif output.shape != shape:
|
|
||||||
raise RuntimeError("output shape not correct")
|
|
||||||
elif complex_output and output.dtype.kind != 'c':
|
|
||||||
raise RuntimeError("output must have complex dtype")
|
|
||||||
return output
|
|
||||||
|
|
||||||
|
|
||||||
def _check_axes(axes, ndim):
|
|
||||||
if axes is None:
|
|
||||||
return tuple(range(ndim))
|
|
||||||
elif np.isscalar(axes):
|
|
||||||
axes = (operator.index(axes),)
|
|
||||||
elif isinstance(axes, Iterable):
|
|
||||||
for ax in axes:
|
|
||||||
axes = tuple(operator.index(ax) for ax in axes)
|
|
||||||
if ax < -ndim or ax > ndim - 1:
|
|
||||||
raise ValueError(f"specified axis: {ax} is out of range")
|
|
||||||
axes = tuple(ax % ndim if ax < 0 else ax for ax in axes)
|
|
||||||
else:
|
|
||||||
message = "axes must be an integer, iterable of integers, or None"
|
|
||||||
raise ValueError(message)
|
|
||||||
if len(tuple(set(axes))) != len(axes):
|
|
||||||
raise ValueError("axes must be unique")
|
|
||||||
return axes
|
|
||||||
@@ -1,10 +0,0 @@
|
|||||||
|
|
||||||
def normalize_axis_index(axis, ndim):
|
|
||||||
# Check if `axis` is in the correct range and normalize it
|
|
||||||
if axis < -ndim or axis >= ndim:
|
|
||||||
msg = f"axis {axis} is out of bounds for array of dimension {ndim}"
|
|
||||||
raise Exception(msg)
|
|
||||||
|
|
||||||
if axis < 0:
|
|
||||||
axis = axis + ndim
|
|
||||||
return axis
|
|
||||||
@@ -1 +0,0 @@
|
|||||||
from ._warps import resize
|
|
||||||
@@ -1,37 +0,0 @@
|
|||||||
import numpy as np
|
|
||||||
|
|
||||||
|
|
||||||
def convert_to_float(image, preserve_range):
|
|
||||||
"""Convert input image to float image with the appropriate range.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
preserve_range : bool
|
|
||||||
Determines if the range of the image should be kept or transformed
|
|
||||||
using img_as_float. Also see
|
|
||||||
https://scikit-image.org/docs/dev/user_guide/data_types.html
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
* Input images with `float32` data type are not upcast.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
image : ndarray
|
|
||||||
Transformed version of the input.
|
|
||||||
|
|
||||||
"""
|
|
||||||
if image.dtype == np.float16:
|
|
||||||
return image.astype(np.float32)
|
|
||||||
if preserve_range:
|
|
||||||
# Convert image to double only if it is not single or double
|
|
||||||
# precision float
|
|
||||||
if image.dtype.char not in 'df':
|
|
||||||
image = image.astype(float)
|
|
||||||
else:
|
|
||||||
from .dtype import img_as_float
|
|
||||||
|
|
||||||
image = img_as_float(image)
|
|
||||||
return image
|
|
||||||
@@ -1,319 +0,0 @@
|
|||||||
import warnings
|
|
||||||
import numpy as np
|
|
||||||
from .. import scipy as ndi
|
|
||||||
from ._utils import convert_to_float
|
|
||||||
|
|
||||||
|
|
||||||
def _clip_warp_output(input_image, output_image, mode, cval, clip):
|
|
||||||
"""Clip output image to range of values of input image.
|
|
||||||
|
|
||||||
Note that this function modifies the values of `output_image` in-place
|
|
||||||
and it is only modified if ``clip=True``.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
input_image : ndarray
|
|
||||||
Input image.
|
|
||||||
output_image : ndarray
|
|
||||||
Output image, which is modified in-place.
|
|
||||||
|
|
||||||
Other parameters
|
|
||||||
----------------
|
|
||||||
mode : {'constant', 'edge', 'symmetric', 'reflect', 'wrap'}
|
|
||||||
Points outside the boundaries of the input are filled according
|
|
||||||
to the given mode. Modes match the behaviour of `numpy.pad`.
|
|
||||||
cval : float
|
|
||||||
Used in conjunction with mode 'constant', the value outside
|
|
||||||
the image boundaries.
|
|
||||||
clip : bool
|
|
||||||
Whether to clip the output to the range of values of the input image.
|
|
||||||
This is enabled by default, since higher order interpolation may
|
|
||||||
produce values outside the given input range.
|
|
||||||
|
|
||||||
"""
|
|
||||||
if clip:
|
|
||||||
min_val = np.min(input_image)
|
|
||||||
if np.isnan(min_val):
|
|
||||||
# NaNs detected, use NaN-safe min/max
|
|
||||||
min_func = np.nanmin
|
|
||||||
max_func = np.nanmax
|
|
||||||
min_val = min_func(input_image)
|
|
||||||
else:
|
|
||||||
min_func = np.min
|
|
||||||
max_func = np.max
|
|
||||||
max_val = max_func(input_image)
|
|
||||||
|
|
||||||
# Check if cval has been used such that it expands the effective input
|
|
||||||
# range
|
|
||||||
preserve_cval = (
|
|
||||||
mode == 'constant'
|
|
||||||
and not min_val <= cval <= max_val
|
|
||||||
and min_func(output_image) <= cval <= max_func(output_image)
|
|
||||||
)
|
|
||||||
|
|
||||||
# expand min/max range to account for cval
|
|
||||||
if preserve_cval:
|
|
||||||
# cast cval to the same dtype as the input image
|
|
||||||
cval = input_image.dtype.type(cval)
|
|
||||||
min_val = min(min_val, cval)
|
|
||||||
max_val = max(max_val, cval)
|
|
||||||
|
|
||||||
# Convert array-like types to ndarrays (gh-7159)
|
|
||||||
min_val, max_val = np.asarray(min_val), np.asarray(max_val)
|
|
||||||
np.clip(output_image, min_val, max_val, out=output_image)
|
|
||||||
|
|
||||||
|
|
||||||
def _validate_interpolation_order(image_dtype, order):
|
|
||||||
"""Validate and return spline interpolation's order.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image_dtype : dtype
|
|
||||||
Image dtype.
|
|
||||||
order : int, optional
|
|
||||||
The order of the spline interpolation. The order has to be in
|
|
||||||
the range 0-5. See `skimage.transform.warp` for detail.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
order : int
|
|
||||||
if input order is None, returns 0 if image_dtype is bool and 1
|
|
||||||
otherwise. Otherwise, image_dtype is checked and input order
|
|
||||||
is validated accordingly (order > 0 is not supported for bool
|
|
||||||
image dtype)
|
|
||||||
|
|
||||||
"""
|
|
||||||
|
|
||||||
if order is None:
|
|
||||||
return 0 if image_dtype == bool else 1
|
|
||||||
|
|
||||||
if order < 0 or order > 5:
|
|
||||||
raise ValueError(
|
|
||||||
"Spline interpolation order has to be in the " "range 0-5.")
|
|
||||||
|
|
||||||
if image_dtype == bool and order != 0:
|
|
||||||
raise ValueError(
|
|
||||||
"Input image dtype is bool. Interpolation is not defined "
|
|
||||||
"with bool data type. Please set order to 0 or explicitly "
|
|
||||||
"cast input image to another data type."
|
|
||||||
)
|
|
||||||
|
|
||||||
return order
|
|
||||||
|
|
||||||
|
|
||||||
def _preprocess_resize_output_shape(image, output_shape):
|
|
||||||
"""Validate resize output shape according to input image.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image: ndarray
|
|
||||||
Image to be resized.
|
|
||||||
output_shape: iterable
|
|
||||||
Size of the generated output image `(rows, cols[, ...][, dim])`. If
|
|
||||||
`dim` is not provided, the number of channels is preserved.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
image: ndarray
|
|
||||||
The input image, but with additional singleton dimensions appended in
|
|
||||||
the case where ``len(output_shape) > input.ndim``.
|
|
||||||
output_shape: tuple
|
|
||||||
The output image converted to tuple.
|
|
||||||
|
|
||||||
Raises
|
|
||||||
------
|
|
||||||
ValueError:
|
|
||||||
If output_shape length is smaller than the image number of
|
|
||||||
dimensions
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The input image is reshaped if its number of dimensions is not
|
|
||||||
equal to output_shape_length.
|
|
||||||
|
|
||||||
"""
|
|
||||||
output_shape = tuple(output_shape)
|
|
||||||
output_ndim = len(output_shape)
|
|
||||||
input_shape = image.shape
|
|
||||||
if output_ndim > image.ndim:
|
|
||||||
# append dimensions to input_shape
|
|
||||||
input_shape += (1,) * (output_ndim - image.ndim)
|
|
||||||
image = np.reshape(image, input_shape)
|
|
||||||
elif output_ndim == image.ndim - 1:
|
|
||||||
# multichannel case: append shape of last axis
|
|
||||||
output_shape = output_shape + (image.shape[-1],)
|
|
||||||
elif output_ndim < image.ndim:
|
|
||||||
raise ValueError(
|
|
||||||
"output_shape length cannot be smaller than the "
|
|
||||||
"image number of dimensions"
|
|
||||||
)
|
|
||||||
|
|
||||||
return image, output_shape
|
|
||||||
|
|
||||||
|
|
||||||
def _to_ndimage_mode(mode):
|
|
||||||
"""Convert from `numpy.pad` mode name to the corresponding ndimage mode."""
|
|
||||||
mode_translation_dict = dict(
|
|
||||||
constant='constant',
|
|
||||||
edge='nearest',
|
|
||||||
symmetric='reflect',
|
|
||||||
reflect='mirror',
|
|
||||||
wrap='wrap',
|
|
||||||
)
|
|
||||||
if mode not in mode_translation_dict:
|
|
||||||
raise ValueError(
|
|
||||||
f"Unknown mode: '{mode}', or cannot translate mode. The "
|
|
||||||
f"mode should be one of 'constant', 'edge', 'symmetric', "
|
|
||||||
f"'reflect', or 'wrap'. See the documentation of numpy.pad for "
|
|
||||||
f"more info."
|
|
||||||
)
|
|
||||||
return _fix_ndimage_mode(mode_translation_dict[mode])
|
|
||||||
|
|
||||||
|
|
||||||
def _fix_ndimage_mode(mode):
|
|
||||||
# SciPy 1.6.0 introduced grid variants of constant and wrap which
|
|
||||||
# have less surprising behavior for images. Use these when available
|
|
||||||
grid_modes = {'constant': 'grid-constant', 'wrap': 'grid-wrap'}
|
|
||||||
return grid_modes.get(mode, mode)
|
|
||||||
|
|
||||||
|
|
||||||
def resize(
|
|
||||||
image,
|
|
||||||
output_shape,
|
|
||||||
order=None,
|
|
||||||
mode='reflect',
|
|
||||||
cval=0,
|
|
||||||
clip=True,
|
|
||||||
preserve_range=False,
|
|
||||||
anti_aliasing=None,
|
|
||||||
anti_aliasing_sigma=None,
|
|
||||||
):
|
|
||||||
"""Resize image to match a certain size.
|
|
||||||
|
|
||||||
Performs interpolation to up-size or down-size N-dimensional images. Note
|
|
||||||
that anti-aliasing should be enabled when down-sizing images to avoid
|
|
||||||
aliasing artifacts. For downsampling with an integer factor also see
|
|
||||||
`skimage.transform.downscale_local_mean`.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
output_shape : iterable
|
|
||||||
Size of the generated output image `(rows, cols[, ...][, dim])`. If
|
|
||||||
`dim` is not provided, the number of channels is preserved. In case the
|
|
||||||
number of input channels does not equal the number of output channels a
|
|
||||||
n-dimensional interpolation is applied.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
resized : ndarray
|
|
||||||
Resized version of the input.
|
|
||||||
|
|
||||||
Other parameters
|
|
||||||
----------------
|
|
||||||
order : int, optional
|
|
||||||
The order of the spline interpolation, default is 0 if
|
|
||||||
image.dtype is bool and 1 otherwise. The order has to be in
|
|
||||||
the range 0-5. See `skimage.transform.warp` for detail.
|
|
||||||
mode : {'constant', 'edge', 'symmetric', 'reflect', 'wrap'}, optional
|
|
||||||
Points outside the boundaries of the input are filled according
|
|
||||||
to the given mode. Modes match the behaviour of `numpy.pad`.
|
|
||||||
cval : float, optional
|
|
||||||
Used in conjunction with mode 'constant', the value outside
|
|
||||||
the image boundaries.
|
|
||||||
clip : bool, optional
|
|
||||||
Whether to clip the output to the range of values of the input image.
|
|
||||||
This is enabled by default, since higher order interpolation may
|
|
||||||
produce values outside the given input range.
|
|
||||||
preserve_range : bool, optional
|
|
||||||
Whether to keep the original range of values. Otherwise, the input
|
|
||||||
image is converted according to the conventions of `img_as_float`.
|
|
||||||
Also see https://scikit-image.org/docs/dev/user_guide/data_types.html
|
|
||||||
anti_aliasing : bool, optional
|
|
||||||
Whether to apply a Gaussian filter to smooth the image prior
|
|
||||||
to downsampling. It is crucial to filter when downsampling
|
|
||||||
the image to avoid aliasing artifacts. If not specified, it is set to
|
|
||||||
True when downsampling an image whose data type is not bool.
|
|
||||||
It is also set to False when using nearest neighbor interpolation
|
|
||||||
(``order`` == 0) with integer input data type.
|
|
||||||
anti_aliasing_sigma : {float, tuple of floats}, optional
|
|
||||||
Standard deviation for Gaussian filtering used when anti-aliasing.
|
|
||||||
By default, this value is chosen as (s - 1) / 2 where s is the
|
|
||||||
downsampling factor, where s > 1. For the up-size case, s < 1, no
|
|
||||||
anti-aliasing is performed prior to rescaling.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
Modes 'reflect' and 'symmetric' are similar, but differ in whether the edge
|
|
||||||
pixels are duplicated during the reflection. As an example, if an array
|
|
||||||
has values [0, 1, 2] and was padded to the right by four values using
|
|
||||||
symmetric, the result would be [0, 1, 2, 2, 1, 0, 0], while for reflect it
|
|
||||||
would be [0, 1, 2, 1, 0, 1, 2].
|
|
||||||
|
|
||||||
Examples
|
|
||||||
--------
|
|
||||||
>>> from skimage import data
|
|
||||||
>>> from skimage.transform import resize
|
|
||||||
>>> image = data.camera()
|
|
||||||
>>> resize(image, (100, 100)).shape
|
|
||||||
(100, 100)
|
|
||||||
|
|
||||||
"""
|
|
||||||
|
|
||||||
image, output_shape = _preprocess_resize_output_shape(image, output_shape)
|
|
||||||
input_shape = image.shape
|
|
||||||
input_type = image.dtype
|
|
||||||
|
|
||||||
if input_type == np.float16:
|
|
||||||
image = image.astype(np.float32)
|
|
||||||
|
|
||||||
if anti_aliasing is None:
|
|
||||||
anti_aliasing = (
|
|
||||||
not input_type == bool
|
|
||||||
and not (np.issubdtype(input_type, np.integer) and order == 0)
|
|
||||||
and any(x < y for x, y in zip(output_shape, input_shape))
|
|
||||||
)
|
|
||||||
|
|
||||||
if input_type == bool and anti_aliasing:
|
|
||||||
raise ValueError("anti_aliasing must be False for boolean images")
|
|
||||||
|
|
||||||
factors = np.divide(input_shape, output_shape)
|
|
||||||
order = _validate_interpolation_order(input_type, order)
|
|
||||||
if order > 0:
|
|
||||||
image = convert_to_float(image, preserve_range)
|
|
||||||
|
|
||||||
# Translate modes used by np.pad to those used by scipy.ndimage
|
|
||||||
ndi_mode = _to_ndimage_mode(mode)
|
|
||||||
if anti_aliasing:
|
|
||||||
if anti_aliasing_sigma is None:
|
|
||||||
anti_aliasing_sigma = np.maximum(0, (factors - 1) / 2)
|
|
||||||
else:
|
|
||||||
anti_aliasing_sigma = np.atleast_1d(anti_aliasing_sigma) * np.ones_like(
|
|
||||||
factors
|
|
||||||
)
|
|
||||||
if np.any(anti_aliasing_sigma < 0):
|
|
||||||
raise ValueError(
|
|
||||||
"Anti-aliasing standard deviation must be "
|
|
||||||
"greater than or equal to zero"
|
|
||||||
)
|
|
||||||
elif np.any((anti_aliasing_sigma > 0) & (factors <= 1)):
|
|
||||||
warnings.warn(
|
|
||||||
"Anti-aliasing standard deviation greater than zero but "
|
|
||||||
"not down-sampling along all axes",
|
|
||||||
stacklevel=2
|
|
||||||
)
|
|
||||||
filtered = ndi.gaussian_filter(
|
|
||||||
image, anti_aliasing_sigma, cval=cval, mode=ndi_mode
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
filtered = image
|
|
||||||
|
|
||||||
zoom_factors = [1 / f for f in factors]
|
|
||||||
out = ndi.zoom(
|
|
||||||
filtered, zoom_factors, order=order, mode=ndi_mode, cval=cval, grid_mode=True
|
|
||||||
)
|
|
||||||
|
|
||||||
_clip_warp_output(image, out, mode, cval, clip)
|
|
||||||
|
|
||||||
return out
|
|
||||||
@@ -1,605 +0,0 @@
|
|||||||
import warnings
|
|
||||||
from warnings import warn
|
|
||||||
|
|
||||||
import numpy as np
|
|
||||||
|
|
||||||
|
|
||||||
__all__ = [
|
|
||||||
'img_as_float32',
|
|
||||||
'img_as_float64',
|
|
||||||
'img_as_float',
|
|
||||||
'img_as_int',
|
|
||||||
'img_as_uint',
|
|
||||||
'img_as_ubyte',
|
|
||||||
'img_as_bool',
|
|
||||||
'dtype_limits',
|
|
||||||
]
|
|
||||||
|
|
||||||
# Some of these may or may not be aliases depending on architecture & platform
|
|
||||||
_integer_types = (
|
|
||||||
np.int8,
|
|
||||||
np.byte,
|
|
||||||
np.int16,
|
|
||||||
np.short,
|
|
||||||
np.int32,
|
|
||||||
np.int64,
|
|
||||||
np.longlong,
|
|
||||||
np.int_,
|
|
||||||
np.intp,
|
|
||||||
np.intc,
|
|
||||||
int,
|
|
||||||
np.uint8,
|
|
||||||
np.ubyte,
|
|
||||||
np.uint16,
|
|
||||||
np.ushort,
|
|
||||||
np.uint32,
|
|
||||||
np.uint64,
|
|
||||||
np.ulonglong,
|
|
||||||
np.uint,
|
|
||||||
np.uintp,
|
|
||||||
np.uintc,
|
|
||||||
)
|
|
||||||
_integer_ranges = {t: (np.iinfo(t).min, np.iinfo(t).max)
|
|
||||||
for t in _integer_types}
|
|
||||||
dtype_range = {
|
|
||||||
bool: (False, True),
|
|
||||||
np.bool_: (False, True),
|
|
||||||
float: (-1, 1),
|
|
||||||
np.float16: (-1, 1),
|
|
||||||
np.float32: (-1, 1),
|
|
||||||
np.float64: (-1, 1),
|
|
||||||
}
|
|
||||||
|
|
||||||
with warnings.catch_warnings():
|
|
||||||
warnings.filterwarnings('ignore', category=DeprecationWarning)
|
|
||||||
|
|
||||||
# np.bool8 is a deprecated alias of np.bool_
|
|
||||||
if hasattr(np, 'bool8'):
|
|
||||||
dtype_range[np.bool8] = (False, True)
|
|
||||||
|
|
||||||
dtype_range.update(_integer_ranges)
|
|
||||||
|
|
||||||
_supported_types = list(dtype_range.keys())
|
|
||||||
|
|
||||||
|
|
||||||
def dtype_limits(image, clip_negative=False):
|
|
||||||
"""Return intensity limits, i.e. (min, max) tuple, of the image's dtype.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
clip_negative : bool, optional
|
|
||||||
If True, clip the negative range (i.e. return 0 for min intensity)
|
|
||||||
even if the image dtype allows negative values.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
imin, imax : tuple
|
|
||||||
Lower and upper intensity limits.
|
|
||||||
"""
|
|
||||||
imin, imax = dtype_range[image.dtype.type]
|
|
||||||
if clip_negative:
|
|
||||||
imin = 0
|
|
||||||
return imin, imax
|
|
||||||
|
|
||||||
|
|
||||||
def _dtype_itemsize(itemsize, *dtypes):
|
|
||||||
"""Return first of `dtypes` with itemsize greater than `itemsize`
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
itemsize: int
|
|
||||||
The data type object element size.
|
|
||||||
|
|
||||||
Other Parameters
|
|
||||||
----------------
|
|
||||||
*dtypes:
|
|
||||||
Any Object accepted by `np.dtype` to be converted to a data
|
|
||||||
type object
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
dtype: data type object
|
|
||||||
First of `dtypes` with itemsize greater than `itemsize`.
|
|
||||||
|
|
||||||
"""
|
|
||||||
return next(dt for dt in dtypes if np.dtype(dt).itemsize >= itemsize)
|
|
||||||
|
|
||||||
|
|
||||||
def _dtype_bits(kind, bits, itemsize=1):
|
|
||||||
"""Return dtype of `kind` that can store a `bits` wide unsigned int
|
|
||||||
|
|
||||||
Parameters:
|
|
||||||
kind: str
|
|
||||||
Data type kind.
|
|
||||||
bits: int
|
|
||||||
Desired number of bits.
|
|
||||||
itemsize: int
|
|
||||||
The data type object element size.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
dtype: data type object
|
|
||||||
Data type of `kind` that can store a `bits` wide unsigned int
|
|
||||||
|
|
||||||
"""
|
|
||||||
|
|
||||||
s = next(
|
|
||||||
i
|
|
||||||
for i in (itemsize,) + (2, 4, 8)
|
|
||||||
if bits < (i * 8) or (bits == (i * 8) and kind == 'u')
|
|
||||||
)
|
|
||||||
|
|
||||||
return np.dtype(kind + str(s))
|
|
||||||
|
|
||||||
|
|
||||||
def _scale(a, n, m, copy=True):
|
|
||||||
"""Scale an array of unsigned/positive integers from `n` to `m` bits.
|
|
||||||
|
|
||||||
Numbers can be represented exactly only if `m` is a multiple of `n`.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
a : ndarray
|
|
||||||
Input image array.
|
|
||||||
n : int
|
|
||||||
Number of bits currently used to encode the values in `a`.
|
|
||||||
m : int
|
|
||||||
Desired number of bits to encode the values in `out`.
|
|
||||||
copy : bool, optional
|
|
||||||
If True, allocates and returns new array. Otherwise, modifies
|
|
||||||
`a` in place.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : array
|
|
||||||
Output image array. Has the same kind as `a`.
|
|
||||||
"""
|
|
||||||
kind = a.dtype.kind
|
|
||||||
if n > m and a.max() < 2**m:
|
|
||||||
mnew = int(np.ceil(m / 2) * 2)
|
|
||||||
if mnew > m:
|
|
||||||
dtype = f'int{mnew}'
|
|
||||||
else:
|
|
||||||
dtype = f'uint{mnew}'
|
|
||||||
n = int(np.ceil(n / 2) * 2)
|
|
||||||
warn(
|
|
||||||
f'Downcasting {a.dtype} to {dtype} without scaling because max '
|
|
||||||
f'value {a.max()} fits in {dtype}',
|
|
||||||
stacklevel=3,
|
|
||||||
)
|
|
||||||
return a.astype(_dtype_bits(kind, m))
|
|
||||||
elif n == m:
|
|
||||||
return a.copy() if copy else a
|
|
||||||
elif n > m:
|
|
||||||
# downscale with precision loss
|
|
||||||
if copy:
|
|
||||||
b = np.empty(a.shape, _dtype_bits(kind, m))
|
|
||||||
np.floor_divide(a, 2 ** (n - m), out=b,
|
|
||||||
dtype=a.dtype, casting='unsafe')
|
|
||||||
return b
|
|
||||||
else:
|
|
||||||
a //= 2 ** (n - m)
|
|
||||||
return a
|
|
||||||
elif m % n == 0:
|
|
||||||
# exact upscale to a multiple of `n` bits
|
|
||||||
if copy:
|
|
||||||
b = np.empty(a.shape, _dtype_bits(kind, m))
|
|
||||||
np.multiply(a, (2**m - 1) // (2**n - 1), out=b, dtype=b.dtype)
|
|
||||||
return b
|
|
||||||
else:
|
|
||||||
a = a.astype(_dtype_bits(kind, m, a.dtype.itemsize), copy=False)
|
|
||||||
a *= (2**m - 1) // (2**n - 1)
|
|
||||||
return a
|
|
||||||
else:
|
|
||||||
# upscale to a multiple of `n` bits,
|
|
||||||
# then downscale with precision loss
|
|
||||||
o = (m // n + 1) * n
|
|
||||||
if copy:
|
|
||||||
b = np.empty(a.shape, _dtype_bits(kind, o))
|
|
||||||
np.multiply(a, (2**o - 1) // (2**n - 1), out=b, dtype=b.dtype)
|
|
||||||
b //= 2 ** (o - m)
|
|
||||||
return b
|
|
||||||
else:
|
|
||||||
a = a.astype(_dtype_bits(kind, o, a.dtype.itemsize), copy=False)
|
|
||||||
a *= (2**o - 1) // (2**n - 1)
|
|
||||||
a //= 2 ** (o - m)
|
|
||||||
return a
|
|
||||||
|
|
||||||
|
|
||||||
def _convert(image, dtype, force_copy=False, uniform=False):
|
|
||||||
"""
|
|
||||||
Convert an image to the requested data-type.
|
|
||||||
|
|
||||||
Warnings are issued in case of precision loss, or when negative values
|
|
||||||
are clipped during conversion to unsigned integer types (sign loss).
|
|
||||||
|
|
||||||
Floating point values are expected to be normalized and will be clipped
|
|
||||||
to the range [0.0, 1.0] or [-1.0, 1.0] when converting to unsigned or
|
|
||||||
signed integers respectively.
|
|
||||||
|
|
||||||
Numbers are not shifted to the negative side when converting from
|
|
||||||
unsigned to signed integer types. Negative values will be clipped when
|
|
||||||
converting to unsigned integers.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
dtype : dtype
|
|
||||||
Target data-type.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
uniform : bool, optional
|
|
||||||
Uniformly quantize the floating point range to the integer range.
|
|
||||||
By default (uniform=False) floating point values are scaled and
|
|
||||||
rounded to the nearest integers, which minimizes back and forth
|
|
||||||
conversion errors.
|
|
||||||
|
|
||||||
.. versionchanged:: 0.15
|
|
||||||
``_convert`` no longer warns about possible precision or sign
|
|
||||||
information loss. See discussions on these warnings at:
|
|
||||||
https://github.com/scikit-image/scikit-image/issues/2602
|
|
||||||
https://github.com/scikit-image/scikit-image/issues/543#issuecomment-208202228
|
|
||||||
https://github.com/scikit-image/scikit-image/pull/3575
|
|
||||||
|
|
||||||
References
|
|
||||||
----------
|
|
||||||
.. [1] DirectX data conversion rules.
|
|
||||||
https://msdn.microsoft.com/en-us/library/windows/desktop/dd607323%28v=vs.85%29.aspx
|
|
||||||
.. [2] Data Conversions. In "OpenGL ES 2.0 Specification v2.0.25",
|
|
||||||
pp 7-8. Khronos Group, 2010.
|
|
||||||
.. [3] Proper treatment of pixels as integers. A.W. Paeth.
|
|
||||||
In "Graphics Gems I", pp 249-256. Morgan Kaufmann, 1990.
|
|
||||||
.. [4] Dirty Pixels. J. Blinn. In "Jim Blinn's corner: Dirty Pixels",
|
|
||||||
pp 47-57. Morgan Kaufmann, 1998.
|
|
||||||
|
|
||||||
"""
|
|
||||||
image = np.asarray(image)
|
|
||||||
dtypeobj_in = image.dtype
|
|
||||||
if dtype is np.floating:
|
|
||||||
dtypeobj_out = np.dtype('float64')
|
|
||||||
else:
|
|
||||||
dtypeobj_out = np.dtype(dtype)
|
|
||||||
dtype_in = dtypeobj_in.type
|
|
||||||
dtype_out = dtypeobj_out.type
|
|
||||||
kind_in = dtypeobj_in.kind
|
|
||||||
kind_out = dtypeobj_out.kind
|
|
||||||
itemsize_in = dtypeobj_in.itemsize
|
|
||||||
itemsize_out = dtypeobj_out.itemsize
|
|
||||||
|
|
||||||
# Below, we do an `issubdtype` check. Its purpose is to find out
|
|
||||||
# whether we can get away without doing any image conversion. This happens
|
|
||||||
# when:
|
|
||||||
#
|
|
||||||
# - the output and input dtypes are the same or
|
|
||||||
# - when the output is specified as a type, and the input dtype
|
|
||||||
# is a subclass of that type (e.g. `np.floating` will allow
|
|
||||||
# `float32` and `float64` arrays through)
|
|
||||||
|
|
||||||
if np.issubdtype(dtype_in, dtype):
|
|
||||||
if force_copy:
|
|
||||||
image = image.copy()
|
|
||||||
return image
|
|
||||||
|
|
||||||
if not (dtype_in in _supported_types and dtype_out in _supported_types):
|
|
||||||
raise ValueError(
|
|
||||||
f'Cannot convert from {dtypeobj_in} to ' f'{dtypeobj_out}.')
|
|
||||||
|
|
||||||
if kind_in in 'ui':
|
|
||||||
imin_in = np.iinfo(dtype_in).min
|
|
||||||
imax_in = np.iinfo(dtype_in).max
|
|
||||||
if kind_out in 'ui':
|
|
||||||
imin_out = np.iinfo(dtype_out).min
|
|
||||||
imax_out = np.iinfo(dtype_out).max
|
|
||||||
|
|
||||||
# any -> binary
|
|
||||||
if kind_out == 'b':
|
|
||||||
return image > dtype_in(dtype_range[dtype_in][1] / 2)
|
|
||||||
|
|
||||||
# binary -> any
|
|
||||||
if kind_in == 'b':
|
|
||||||
result = image.astype(dtype_out)
|
|
||||||
if kind_out != 'f':
|
|
||||||
result *= dtype_out(dtype_range[dtype_out][1])
|
|
||||||
return result
|
|
||||||
|
|
||||||
# float -> any
|
|
||||||
if kind_in == 'f':
|
|
||||||
if kind_out == 'f':
|
|
||||||
# float -> float
|
|
||||||
return image.astype(dtype_out)
|
|
||||||
|
|
||||||
if np.min(image) < -1.0 or np.max(image) > 1.0:
|
|
||||||
raise ValueError("Images of type float must be between -1 and 1.")
|
|
||||||
# floating point -> integer
|
|
||||||
# use float type that can represent output integer type
|
|
||||||
computation_type = _dtype_itemsize(
|
|
||||||
itemsize_out, dtype_in, np.float32, np.float64
|
|
||||||
)
|
|
||||||
|
|
||||||
if not uniform:
|
|
||||||
if kind_out == 'u':
|
|
||||||
image_out = np.multiply(
|
|
||||||
image, imax_out, dtype=computation_type)
|
|
||||||
else:
|
|
||||||
image_out = np.multiply(
|
|
||||||
image, (imax_out - imin_out) / 2, dtype=computation_type
|
|
||||||
)
|
|
||||||
image_out -= 1.0 / 2.0
|
|
||||||
np.rint(image_out, out=image_out)
|
|
||||||
np.clip(image_out, imin_out, imax_out, out=image_out)
|
|
||||||
elif kind_out == 'u':
|
|
||||||
image_out = np.multiply(
|
|
||||||
image, imax_out + 1, dtype=computation_type)
|
|
||||||
np.clip(image_out, 0, imax_out, out=image_out)
|
|
||||||
else:
|
|
||||||
image_out = np.multiply(
|
|
||||||
image, (imax_out - imin_out + 1.0) / 2.0, dtype=computation_type
|
|
||||||
)
|
|
||||||
np.floor(image_out, out=image_out)
|
|
||||||
np.clip(image_out, imin_out, imax_out, out=image_out)
|
|
||||||
return image_out.astype(dtype_out)
|
|
||||||
|
|
||||||
# signed/unsigned int -> float
|
|
||||||
if kind_out == 'f':
|
|
||||||
# use float type that can exactly represent input integers
|
|
||||||
computation_type = _dtype_itemsize(
|
|
||||||
itemsize_in, dtype_out, np.float32, np.float64
|
|
||||||
)
|
|
||||||
|
|
||||||
if kind_in == 'u':
|
|
||||||
# using np.divide or np.multiply doesn't copy the data
|
|
||||||
# until the computation time
|
|
||||||
image = np.multiply(image, 1.0 / imax_in, dtype=computation_type)
|
|
||||||
# DirectX uses this conversion also for signed ints
|
|
||||||
# if imin_in:
|
|
||||||
# np.maximum(image, -1.0, out=image)
|
|
||||||
elif kind_in == 'i':
|
|
||||||
# From DirectX conversions:
|
|
||||||
# The most negative value maps to -1.0f
|
|
||||||
# Every other value is converted to a float (call it c)
|
|
||||||
# and then result = c * (1.0f / (2⁽ⁿ⁻¹⁾-1)).
|
|
||||||
|
|
||||||
image = np.multiply(image, 1.0 / imax_in, dtype=computation_type)
|
|
||||||
np.maximum(image, -1.0, out=image)
|
|
||||||
|
|
||||||
else:
|
|
||||||
image = np.add(image, 0.5, dtype=computation_type)
|
|
||||||
image *= 2 / (imax_in - imin_in)
|
|
||||||
|
|
||||||
return np.asarray(image, dtype_out)
|
|
||||||
|
|
||||||
# unsigned int -> signed/unsigned int
|
|
||||||
if kind_in == 'u':
|
|
||||||
if kind_out == 'i':
|
|
||||||
# unsigned int -> signed int
|
|
||||||
image = _scale(image, 8 * itemsize_in, 8 * itemsize_out - 1)
|
|
||||||
return image.view(dtype_out)
|
|
||||||
else:
|
|
||||||
# unsigned int -> unsigned int
|
|
||||||
return _scale(image, 8 * itemsize_in, 8 * itemsize_out)
|
|
||||||
|
|
||||||
# signed int -> unsigned int
|
|
||||||
if kind_out == 'u':
|
|
||||||
image = _scale(image, 8 * itemsize_in - 1, 8 * itemsize_out)
|
|
||||||
result = np.empty(image.shape, dtype_out)
|
|
||||||
np.maximum(image, 0, out=result, dtype=image.dtype, casting='unsafe')
|
|
||||||
return result
|
|
||||||
|
|
||||||
# signed int -> signed int
|
|
||||||
if itemsize_in > itemsize_out:
|
|
||||||
return _scale(image, 8 * itemsize_in - 1, 8 * itemsize_out - 1)
|
|
||||||
|
|
||||||
image = image.astype(_dtype_bits('i', itemsize_out * 8))
|
|
||||||
image -= imin_in
|
|
||||||
image = _scale(image, 8 * itemsize_in, 8 * itemsize_out, copy=False)
|
|
||||||
image += imin_out
|
|
||||||
return image.astype(dtype_out)
|
|
||||||
|
|
||||||
|
|
||||||
def convert(image, dtype, force_copy=False, uniform=False):
|
|
||||||
warn(
|
|
||||||
"The use of this function is discouraged as its behavior may change "
|
|
||||||
"dramatically in scikit-image 1.0. This function will be removed "
|
|
||||||
"in scikit-image 1.0.",
|
|
||||||
FutureWarning,
|
|
||||||
stacklevel=2,
|
|
||||||
)
|
|
||||||
return _convert(image=image, dtype=dtype, force_copy=force_copy, uniform=uniform)
|
|
||||||
|
|
||||||
|
|
||||||
if _convert.__doc__ is not None:
|
|
||||||
convert.__doc__ = (
|
|
||||||
_convert.__doc__
|
|
||||||
+ """
|
|
||||||
|
|
||||||
Warns
|
|
||||||
-----
|
|
||||||
FutureWarning:
|
|
||||||
.. versionadded:: 0.17
|
|
||||||
|
|
||||||
The use of this function is discouraged as its behavior may change
|
|
||||||
dramatically in scikit-image 1.0. This function will be removed
|
|
||||||
in scikit-image 1.0.
|
|
||||||
"""
|
|
||||||
)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_float32(image, force_copy=False):
|
|
||||||
"""Convert an image to single-precision (32-bit) floating point format.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of float32
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The range of a floating point image is [0.0, 1.0] or [-1.0, 1.0] when
|
|
||||||
converting from unsigned or signed datatypes, respectively.
|
|
||||||
If the input image has a float type, intensity values are not modified
|
|
||||||
and can be outside the ranges [0.0, 1.0] or [-1.0, 1.0].
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, np.float32, force_copy)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_float64(image, force_copy=False):
|
|
||||||
"""Convert an image to double-precision (64-bit) floating point format.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of float64
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The range of a floating point image is [0.0, 1.0] or [-1.0, 1.0] when
|
|
||||||
converting from unsigned or signed datatypes, respectively.
|
|
||||||
If the input image has a float type, intensity values are not modified
|
|
||||||
and can be outside the ranges [0.0, 1.0] or [-1.0, 1.0].
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, np.float64, force_copy)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_float(image, force_copy=False):
|
|
||||||
"""Convert an image to floating point format.
|
|
||||||
|
|
||||||
This function is similar to `img_as_float64`, but will not convert
|
|
||||||
lower-precision floating point arrays to `float64`.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of float
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The range of a floating point image is [0.0, 1.0] or [-1.0, 1.0] when
|
|
||||||
converting from unsigned or signed datatypes, respectively.
|
|
||||||
If the input image has a float type, intensity values are not modified
|
|
||||||
and can be outside the ranges [0.0, 1.0] or [-1.0, 1.0].
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, np.floating, force_copy)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_uint(image, force_copy=False):
|
|
||||||
"""Convert an image to 16-bit unsigned integer format.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of uint16
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
Negative input values will be clipped.
|
|
||||||
Positive values are scaled between 0 and 65535.
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, np.uint16, force_copy)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_int(image, force_copy=False):
|
|
||||||
"""Convert an image to 16-bit signed integer format.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of int16
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The values are scaled between -32768 and 32767.
|
|
||||||
If the input data-type is positive-only (e.g., uint8), then
|
|
||||||
the output image will still only have positive values.
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, np.int16, force_copy)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_ubyte(image, force_copy=False):
|
|
||||||
"""Convert an image to 8-bit unsigned integer format.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of ubyte (uint8)
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
Negative input values will be clipped.
|
|
||||||
Positive values are scaled between 0 and 255.
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, np.uint8, force_copy)
|
|
||||||
|
|
||||||
|
|
||||||
def img_as_bool(image, force_copy=False):
|
|
||||||
"""Convert an image to boolean format.
|
|
||||||
|
|
||||||
Parameters
|
|
||||||
----------
|
|
||||||
image : ndarray
|
|
||||||
Input image.
|
|
||||||
force_copy : bool, optional
|
|
||||||
Force a copy of the data, irrespective of its current dtype.
|
|
||||||
|
|
||||||
Returns
|
|
||||||
-------
|
|
||||||
out : ndarray of bool (`bool_`)
|
|
||||||
Output image.
|
|
||||||
|
|
||||||
Notes
|
|
||||||
-----
|
|
||||||
The upper half of the input dtype's positive range is True, and the lower
|
|
||||||
half is False. All negative values (if present) are False.
|
|
||||||
|
|
||||||
"""
|
|
||||||
return _convert(image, bool, force_copy)
|
|
||||||
@@ -1,12 +1,12 @@
|
|||||||
schema_version = "1.0.0"
|
schema_version = "1.0.0"
|
||||||
|
|
||||||
id = "bioxelnodes"
|
id = "bioxelnodes"
|
||||||
version = "2.0.0"
|
version = "2.0.1"
|
||||||
name = "Bioxel Nodes"
|
name = "Bioxel Nodes"
|
||||||
tagline = "For scientific volumetric data visualization in Blender"
|
tagline = "For scientific volumetric data visualization in Blender"
|
||||||
maintainer = "Nan <icrdr2010@outlook.com>"
|
maintainer = "Nan <icrdr2010@outlook.com>"
|
||||||
type = "add-on"
|
type = "add-on"
|
||||||
website = "https://omoolab.github.io/BioxelNodes/latest"
|
website = "https://docs.omoolab.xyz/bioxelnodes/"
|
||||||
|
|
||||||
tags = ["Geometry Nodes", "Render", "Import-Export"]
|
tags = ["Geometry Nodes", "Render", "Import-Export"]
|
||||||
blender_version_min = "5.0.0"
|
blender_version_min = "5.0.0"
|
||||||
@@ -29,12 +29,13 @@ wheels = [
|
|||||||
"./wheels/matplotlib-3.10.7-cp311-cp311-win_amd64.whl",
|
"./wheels/matplotlib-3.10.7-cp311-cp311-win_amd64.whl",
|
||||||
"./wheels/matplotlib-3.10.7-cp313-cp313-win_amd64.whl",
|
"./wheels/matplotlib-3.10.7-cp313-cp313-win_amd64.whl",
|
||||||
"./wheels/mrcfile-1.5.1-py2.py3-none-any.whl",
|
"./wheels/mrcfile-1.5.1-py2.py3-none-any.whl",
|
||||||
"./wheels/packaging-26.2-py3-none-any.whl",
|
|
||||||
"./wheels/pillow-11.2.1-cp311-cp311-win_amd64.whl",
|
"./wheels/pillow-11.2.1-cp311-cp311-win_amd64.whl",
|
||||||
"./wheels/pillow-11.2.1-cp313-cp313-win_amd64.whl",
|
"./wheels/pillow-11.2.1-cp313-cp313-win_amd64.whl",
|
||||||
"./wheels/pyometiff-1.0.0-py3-none-any.whl",
|
"./wheels/pyometiff-1.0.0-py3-none-any.whl",
|
||||||
"./wheels/pyparsing-3.3.2-py3-none-any.whl",
|
"./wheels/pyparsing-3.3.2-py3-none-any.whl",
|
||||||
"./wheels/python_dateutil-2.9.0.post0-py2.py3-none-any.whl",
|
"./wheels/python_dateutil-2.9.0.post0-py2.py3-none-any.whl",
|
||||||
|
"./wheels/scipy-1.17.1-cp311-cp311-win_amd64.whl",
|
||||||
|
"./wheels/scipy-1.17.1-cp313-cp313-win_amd64.whl",
|
||||||
"./wheels/simpleitk-2.5.5-cp311-abi3-win_amd64.whl",
|
"./wheels/simpleitk-2.5.5-cp311-abi3-win_amd64.whl",
|
||||||
"./wheels/six-1.17.0-py2.py3-none-any.whl",
|
"./wheels/six-1.17.0-py2.py3-none-any.whl",
|
||||||
"./wheels/tifffile-2024.7.24-py3-none-any.whl",
|
"./wheels/tifffile-2024.7.24-py3-none-any.whl",
|
||||||
|
|||||||
@@ -227,20 +227,18 @@ def set_layer_caches(layers_data: List[Dict[str, Any]]):
|
|||||||
layers_text.write(json.dumps(layers_data, indent=4))
|
layers_text.write(json.dumps(layers_data, indent=4))
|
||||||
|
|
||||||
|
|
||||||
def save_layers_to_json(layers: List[Layer], cache_dir: str) -> List[int]:
|
def save_layers_to_cache(layers: List[Layer], cache_dir: str) -> List[Dict[str, Any]]:
|
||||||
"""
|
"""
|
||||||
Save multiple Layer objects into the internal layers text datablock.
|
Save multiple Layer objects into cache folders.
|
||||||
|
|
||||||
For each layer:
|
For each layer:
|
||||||
- Generates a unique cache id.
|
- Generates a unique cache id.
|
||||||
- Writes VDB files and a low-resolution snapshot (.npy) plus PNG slices under cache_dir/<cache_id>/.
|
- Writes VDB files and a low-resolution snapshot (.npy) plus PNG slices under cache_dir/<cache_id>/.
|
||||||
- Appends an entry describing the layer into the b i o x e l _ l a y e r s text datablock.
|
|
||||||
|
|
||||||
Returns:
|
Returns:
|
||||||
- List of generated cache ids for the saved layers.
|
- List of layer cache metadata dictionaries.
|
||||||
"""
|
"""
|
||||||
existing_data = get_layer_caches()
|
cache_infos = []
|
||||||
added_ids = []
|
|
||||||
|
|
||||||
cache_dir_path = Path(cache_dir)
|
cache_dir_path = Path(cache_dir)
|
||||||
cache_dir_path.mkdir(parents=True, exist_ok=True)
|
cache_dir_path.mkdir(parents=True, exist_ok=True)
|
||||||
@@ -270,8 +268,22 @@ def save_layers_to_json(layers: List[Layer], cache_dir: str) -> List[int]:
|
|||||||
"snapshot_z": 0.5,
|
"snapshot_z": 0.5,
|
||||||
}
|
}
|
||||||
|
|
||||||
|
cache_infos.append(cache_info)
|
||||||
|
|
||||||
|
return cache_infos
|
||||||
|
|
||||||
|
|
||||||
|
def save_layers_to_json(layers: List[Layer], cache_dir: str) -> List[int]:
|
||||||
|
"""
|
||||||
|
Save multiple Layer objects into cache folders and the internal layers text datablock.
|
||||||
|
"""
|
||||||
|
existing_data = get_layer_caches()
|
||||||
|
cache_infos = save_layers_to_cache(layers, cache_dir)
|
||||||
|
|
||||||
|
added_ids = []
|
||||||
|
for cache_info in cache_infos:
|
||||||
existing_data.append(cache_info)
|
existing_data.append(cache_info)
|
||||||
added_ids.append(cache_id)
|
added_ids.append(cache_info["id"])
|
||||||
|
|
||||||
set_layer_caches(existing_data)
|
set_layer_caches(existing_data)
|
||||||
print(f"Successfully added {len(added_ids)} layers to the internal text datablock")
|
print(f"Successfully added {len(added_ids)} layers to the internal text datablock")
|
||||||
|
|||||||
@@ -1,22 +1,22 @@
|
|||||||
|
import json
|
||||||
import math
|
import math
|
||||||
import shutil
|
import shutil
|
||||||
import threading
|
import subprocess
|
||||||
|
import tempfile
|
||||||
from pathlib import Path
|
from pathlib import Path
|
||||||
|
|
||||||
import bpy
|
import bpy
|
||||||
import numpy as np
|
import numpy as np
|
||||||
import SimpleITK as sitk
|
import SimpleITK as sitk
|
||||||
import transforms3d
|
|
||||||
|
|
||||||
# KeyboardInterrupt replaced with built-in KeyboardInterrupt
|
# KeyboardInterrupt replaced with built-in KeyboardInterrupt
|
||||||
from ..props import BIOXEL_Series
|
from ..props import BIOXEL_Series
|
||||||
from ..utils import get_layer_obj, wrapped_label
|
from ..utils import get_layer_obj, wrapped_label
|
||||||
|
|
||||||
from ..bioxel.layer import Layer
|
from ..bioxel.parse import DICOM_EXTS, SUPPORT_EXTS, get_ext
|
||||||
from ..bioxel.parse import DICOM_EXTS, SUPPORT_EXTS, get_ext, parse_volumetric_data
|
|
||||||
|
|
||||||
from ..utils import get_cache_dir, progress_update, progress_bar
|
from ..utils import get_cache_dir, progress_update, progress_bar
|
||||||
from ..layer import get_layer_caches, save_layers_to_json
|
from ..layer import get_layer_caches, set_layer_caches
|
||||||
|
|
||||||
|
|
||||||
def get_layer_shape(bioxel_size: float, orig_shape: tuple, orig_spacing: tuple):
|
def get_layer_shape(bioxel_size: float, orig_shape: tuple, orig_spacing: tuple):
|
||||||
@@ -43,6 +43,90 @@ def get_layer_size(shape: tuple, bioxel_size: float, scale: float = 1.0):
|
|||||||
return size
|
return size
|
||||||
|
|
||||||
|
|
||||||
|
def write_worker_json(path: Path, data):
|
||||||
|
path.write_text(json.dumps(data), encoding="utf-8")
|
||||||
|
|
||||||
|
|
||||||
|
def read_worker_json(path: Path):
|
||||||
|
try:
|
||||||
|
return json.loads(path.read_text(encoding="utf-8"))
|
||||||
|
except Exception:
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def remove_progress_bar_safe():
|
||||||
|
try:
|
||||||
|
bpy.types.STATUSBAR_HT_header.remove(progress_bar)
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
def start_worker_process(owner, command: str, payload: dict):
|
||||||
|
job_dir = Path(tempfile.mkdtemp(prefix="bioxel_import_", dir=str(get_cache_dir())))
|
||||||
|
config_path = job_dir / "config.json"
|
||||||
|
progress_path = job_dir / "progress.json"
|
||||||
|
result_path = job_dir / "result.json"
|
||||||
|
cancel_path = job_dir / "cancel"
|
||||||
|
log_path = job_dir / "worker.log"
|
||||||
|
|
||||||
|
config = {
|
||||||
|
**payload,
|
||||||
|
"command": command,
|
||||||
|
"progress_path": str(progress_path),
|
||||||
|
"result_path": str(result_path),
|
||||||
|
"cancel_path": str(cancel_path),
|
||||||
|
}
|
||||||
|
write_worker_json(config_path, config)
|
||||||
|
write_worker_json(progress_path, {"factor": 0.0, "text": "Starting..."})
|
||||||
|
|
||||||
|
worker_path = Path(__file__).with_name("io_worker.py")
|
||||||
|
cmd = [
|
||||||
|
bpy.app.binary_path,
|
||||||
|
"--background",
|
||||||
|
"--factory-startup",
|
||||||
|
"--python",
|
||||||
|
str(worker_path),
|
||||||
|
"--",
|
||||||
|
str(config_path),
|
||||||
|
]
|
||||||
|
|
||||||
|
creationflags = getattr(subprocess, "CREATE_NO_WINDOW", 0)
|
||||||
|
log_file = log_path.open("w", encoding="utf-8")
|
||||||
|
try:
|
||||||
|
owner.process = subprocess.Popen(
|
||||||
|
cmd,
|
||||||
|
stdout=log_file,
|
||||||
|
stderr=subprocess.STDOUT,
|
||||||
|
creationflags=creationflags,
|
||||||
|
)
|
||||||
|
finally:
|
||||||
|
log_file.close()
|
||||||
|
|
||||||
|
owner.job_dir = job_dir
|
||||||
|
owner.progress_path = progress_path
|
||||||
|
owner.result_path = result_path
|
||||||
|
owner.cancel_path = cancel_path
|
||||||
|
owner.log_path = log_path
|
||||||
|
|
||||||
|
|
||||||
|
def cancel_worker_process(owner, context):
|
||||||
|
owner.is_cancelled = True
|
||||||
|
try:
|
||||||
|
owner.cancel_path.write_text("cancel", encoding="utf-8")
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
progress_update(context, 0.0, "Canceling...")
|
||||||
|
|
||||||
|
|
||||||
|
def update_worker_progress(owner, context):
|
||||||
|
progress = read_worker_json(owner.progress_path)
|
||||||
|
if progress:
|
||||||
|
progress_update(
|
||||||
|
context,
|
||||||
|
float(progress.get("factor", 0.0)),
|
||||||
|
progress.get("text", ""),
|
||||||
|
)
|
||||||
|
|
||||||
"""
|
"""
|
||||||
ImportData -> ParseVolumetricData -> ImportDataDialog
|
ImportData -> ParseVolumetricData -> ImportDataDialog
|
||||||
start import parse data execute import
|
start import parse data execute import
|
||||||
@@ -167,7 +251,12 @@ class ParseVolumetricData(bpy.types.Operator):
|
|||||||
meta = None
|
meta = None
|
||||||
label_count = 0
|
label_count = 0
|
||||||
dtype = None
|
dtype = None
|
||||||
thread = None
|
process = None
|
||||||
|
job_dir = None
|
||||||
|
progress_path = None
|
||||||
|
result_path = None
|
||||||
|
cancel_path = None
|
||||||
|
log_path = None
|
||||||
_timer = None
|
_timer = None
|
||||||
|
|
||||||
progress: bpy.props.FloatProperty(
|
progress: bpy.props.FloatProperty(
|
||||||
@@ -202,97 +291,64 @@ class ParseVolumetricData(bpy.types.Operator):
|
|||||||
|
|
||||||
def execute(self, context):
|
def execute(self, context):
|
||||||
print("Collecting Meta Data...")
|
print("Collecting Meta Data...")
|
||||||
|
|
||||||
def parse_volumetric_data_func(self, context, cancel):
|
|
||||||
def progress_callback(factor, text):
|
|
||||||
if cancel():
|
|
||||||
raise KeyboardInterrupt("Cancelled by user")
|
|
||||||
progress_update(context, factor, text)
|
|
||||||
|
|
||||||
try:
|
|
||||||
series_id = self.series_id if self.series_id != "empty" else ""
|
|
||||||
data, meta = parse_volumetric_data(
|
|
||||||
data_file=self.filepath,
|
|
||||||
series_id=series_id,
|
|
||||||
progress_callback=progress_callback,
|
|
||||||
)
|
|
||||||
except KeyboardInterrupt:
|
|
||||||
return
|
|
||||||
except Exception as e:
|
|
||||||
self.has_error = e
|
|
||||||
return
|
|
||||||
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
self.meta = meta
|
|
||||||
self.label_count = int(np.max(data))
|
|
||||||
self.dtype = data.dtype
|
|
||||||
|
|
||||||
# Init cancel flag
|
|
||||||
self.is_cancelled = False
|
self.is_cancelled = False
|
||||||
self.has_error = None
|
self.has_error = None
|
||||||
|
self.meta = None
|
||||||
|
self.label_count = 0
|
||||||
|
self.dtype = None
|
||||||
|
|
||||||
# Create the thread
|
start_worker_process(
|
||||||
self.thread = threading.Thread(
|
self,
|
||||||
target=parse_volumetric_data_func,
|
"read_meta",
|
||||||
args=(self, context, lambda: self.is_cancelled),
|
{
|
||||||
|
"filepath": self.filepath,
|
||||||
|
"series_id": self.series_id,
|
||||||
|
},
|
||||||
)
|
)
|
||||||
|
|
||||||
# Start the thread
|
|
||||||
self.thread.start()
|
|
||||||
# Add a timmer for modal
|
|
||||||
self._timer = context.window_manager.event_timer_add(
|
self._timer = context.window_manager.event_timer_add(
|
||||||
time_step=0.1, window=context.window
|
time_step=0.1, window=context.window
|
||||||
)
|
)
|
||||||
# Append progress bar to status bar
|
|
||||||
bpy.types.STATUSBAR_HT_header.append(progress_bar)
|
bpy.types.STATUSBAR_HT_header.append(progress_bar)
|
||||||
|
|
||||||
# Start modal handler
|
|
||||||
context.window_manager.modal_handler_add(self)
|
context.window_manager.modal_handler_add(self)
|
||||||
return {"RUNNING_MODAL"}
|
return {"RUNNING_MODAL"}
|
||||||
|
|
||||||
def modal(self, context, event):
|
def modal(self, context, event):
|
||||||
# Check if user press 'ESC'
|
|
||||||
if event.type == "ESC":
|
if event.type == "ESC":
|
||||||
self.is_cancelled = True
|
cancel_worker_process(self, context)
|
||||||
progress_update(context, 0.0, "Canceling...")
|
|
||||||
return {"PASS_THROUGH"}
|
return {"PASS_THROUGH"}
|
||||||
|
|
||||||
# Check if is the timer time
|
|
||||||
if event.type != "TIMER":
|
if event.type != "TIMER":
|
||||||
return {"PASS_THROUGH"}
|
return {"PASS_THROUGH"}
|
||||||
|
|
||||||
# Force update status bar
|
|
||||||
bpy.context.workspace.status_text_set_internal(None)
|
bpy.context.workspace.status_text_set_internal(None)
|
||||||
|
update_worker_progress(self, context)
|
||||||
|
|
||||||
# Check if thread is still running
|
if self.process.poll() is None:
|
||||||
if self.thread.is_alive():
|
|
||||||
return {"PASS_THROUGH"}
|
return {"PASS_THROUGH"}
|
||||||
|
|
||||||
# Release the thread
|
|
||||||
self.thread.join()
|
|
||||||
# Remove the timer
|
|
||||||
context.window_manager.event_timer_remove(self._timer)
|
context.window_manager.event_timer_remove(self._timer)
|
||||||
# Remove the progress bar from status bar
|
remove_progress_bar_safe()
|
||||||
bpy.types.STATUSBAR_HT_header.remove(progress_bar)
|
|
||||||
progress_update(context, 1.0)
|
progress_update(context, 1.0)
|
||||||
|
|
||||||
# Check if thread is cancelled by user
|
result = read_worker_json(self.result_path)
|
||||||
if self.is_cancelled:
|
if self.is_cancelled or (result and result.get("cancelled")):
|
||||||
self.report({"WARNING"}, "Canncelled by user.")
|
self.report({"WARNING"}, "Canncelled by user.")
|
||||||
return {"CANCELLED"}
|
return {"CANCELLED"}
|
||||||
|
|
||||||
# Check if thread is cancelled by user
|
if not result:
|
||||||
if self.has_error:
|
self.report({"ERROR"}, f"Import worker failed. See log: {self.log_path}")
|
||||||
raise self.has_error
|
|
||||||
|
|
||||||
# Check if has return
|
|
||||||
if self.meta is None:
|
|
||||||
self.report({"ERROR"}, "Some thing went wrong.")
|
|
||||||
return {"CANCELLED"}
|
return {"CANCELLED"}
|
||||||
|
|
||||||
# If not canncelled...
|
if not result.get("ok"):
|
||||||
|
print(result.get("traceback", ""))
|
||||||
|
self.report({"ERROR"}, result.get("error", "Import worker failed."))
|
||||||
|
return {"CANCELLED"}
|
||||||
|
|
||||||
|
self.meta = result["meta"]
|
||||||
|
self.label_count = int(result["label_count"])
|
||||||
|
self.dtype = np.dtype(result["dtype"])
|
||||||
|
|
||||||
for key, value in self.meta.items():
|
for key, value in self.meta.items():
|
||||||
print(f"{key}: {value}")
|
print(f"{key}: {value}")
|
||||||
|
|
||||||
@@ -310,8 +366,6 @@ class ParseVolumetricData(bpy.types.Operator):
|
|||||||
|
|
||||||
min_log10 = math.floor(math.log10(min(*orig_spacing)))
|
min_log10 = math.floor(math.log10(min(*orig_spacing)))
|
||||||
max_log10 = math.floor(math.log10(max(*orig_spacing)))
|
max_log10 = math.floor(math.log10(max(*orig_spacing)))
|
||||||
# min_space = min(*orig_spacing)
|
|
||||||
# max_space = max(*orig_spacing)
|
|
||||||
|
|
||||||
if orig_spacing[2] == 1 and min_log10 < -1:
|
if orig_spacing[2] == 1 and min_log10 < -1:
|
||||||
orig_spacing = (
|
orig_spacing = (
|
||||||
@@ -493,8 +547,14 @@ class ImportDataDialog(bpy.types.Operator):
|
|||||||
bl_description = "Import Volumetric Data as Layer"
|
bl_description = "Import Volumetric Data as Layer"
|
||||||
bl_options = {"UNDO"}
|
bl_options = {"UNDO"}
|
||||||
|
|
||||||
layers = None
|
cache_infos = None
|
||||||
thread = None
|
added_ids = None
|
||||||
|
process = None
|
||||||
|
job_dir = None
|
||||||
|
progress_path = None
|
||||||
|
result_path = None
|
||||||
|
cancel_path = None
|
||||||
|
log_path = None
|
||||||
_timer = None
|
_timer = None
|
||||||
|
|
||||||
filepath: bpy.props.StringProperty(subtype="FILE_PATH") # type: ignore
|
filepath: bpy.props.StringProperty(subtype="FILE_PATH") # type: ignore
|
||||||
@@ -546,253 +606,31 @@ class ImportDataDialog(bpy.types.Operator):
|
|||||||
) # type: ignore
|
) # type: ignore
|
||||||
|
|
||||||
def execute(self, context):
|
def execute(self, context):
|
||||||
def import_volumetric_data_func(self, context, cancel):
|
|
||||||
progress_update(context, 0.0, "Parsing Volumetirc Data...")
|
|
||||||
|
|
||||||
def progress_callback(factor, text):
|
|
||||||
if cancel():
|
|
||||||
raise KeyboardInterrupt("Cancelled by user")
|
|
||||||
progress_update(context, factor * 0.2, text)
|
|
||||||
|
|
||||||
def progress_callback_factory(layer_name, progress, progress_step):
|
|
||||||
def progress_callback(frame, total):
|
|
||||||
if cancel():
|
|
||||||
raise KeyboardInterrupt("Cancelled by user")
|
|
||||||
sub_progress_step = progress_step / total
|
|
||||||
sub_progress = progress + frame * sub_progress_step
|
|
||||||
progress_update(
|
|
||||||
context,
|
|
||||||
sub_progress,
|
|
||||||
f"Processing {layer_name} Frame {frame+1}...",
|
|
||||||
)
|
|
||||||
print(f"Processing {layer_name} Frame {frame+1}...")
|
|
||||||
|
|
||||||
return progress_callback
|
|
||||||
|
|
||||||
try:
|
|
||||||
data, meta = parse_volumetric_data(
|
|
||||||
data_file=self.filepath,
|
|
||||||
series_id=self.series_id,
|
|
||||||
progress_callback=progress_callback,
|
|
||||||
)
|
|
||||||
|
|
||||||
except KeyboardInterrupt:
|
|
||||||
return
|
|
||||||
except Exception as e:
|
|
||||||
self.has_error = e
|
|
||||||
return
|
|
||||||
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
shape = get_layer_shape(
|
|
||||||
self.bioxel_size, self.orig_shape, self.orig_spacing
|
|
||||||
)
|
|
||||||
|
|
||||||
mat_scale = transforms3d.zooms.zfdir2aff(self.bioxel_size)
|
|
||||||
affine = np.dot(meta["affine"], mat_scale)
|
|
||||||
kind = self.read_as.lower()
|
|
||||||
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
# change shape as sequence or not
|
|
||||||
if self.frame_source == "-1":
|
|
||||||
data = data[0:1, :, :, :, :]
|
|
||||||
elif self.frame_source == "0":
|
|
||||||
# frame as frame
|
|
||||||
pass
|
|
||||||
elif self.frame_source == "1":
|
|
||||||
# X as frame
|
|
||||||
data = data.transpose(1, 0, 2, 3, 4)
|
|
||||||
shape = (1, shape[1], shape[2])
|
|
||||||
elif self.frame_source == "2":
|
|
||||||
# Y as frame
|
|
||||||
data = data.transpose(2, 1, 0, 3, 4)
|
|
||||||
shape = (shape[0], 1, shape[2])
|
|
||||||
elif self.frame_source == "3":
|
|
||||||
# Z as frame
|
|
||||||
data = data.transpose(3, 1, 2, 0, 4)
|
|
||||||
shape = (shape[0], shape[1], 1)
|
|
||||||
else:
|
|
||||||
# channel as frame
|
|
||||||
data = data.transpose(4, 1, 2, 3, 0)
|
|
||||||
|
|
||||||
layers = []
|
|
||||||
if kind == "label":
|
|
||||||
name = self.layer_name or "Label"
|
|
||||||
data = data.astype(int)
|
|
||||||
label_count = int(np.max(data))
|
|
||||||
progress_step = 0.7 / label_count
|
|
||||||
|
|
||||||
for i in range(label_count):
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
name_i = f"{name}_{i+1}"
|
|
||||||
progress = 0.2 + i * progress_step
|
|
||||||
progress_update(context, progress, f"Processing {name_i}...")
|
|
||||||
|
|
||||||
progress_callback = progress_callback_factory(
|
|
||||||
name_i, progress, progress_step
|
|
||||||
)
|
|
||||||
label_data = data == np.full_like(data, i + 1)
|
|
||||||
# label_data = label_data.astype(np.float32)
|
|
||||||
try:
|
|
||||||
layer = Layer(data=label_data, name=name_i, kind=kind)
|
|
||||||
|
|
||||||
layer.resize(
|
|
||||||
shape=shape,
|
|
||||||
smooth=self.smooth,
|
|
||||||
progress_callback=progress_callback,
|
|
||||||
)
|
|
||||||
|
|
||||||
layer.affine = affine
|
|
||||||
|
|
||||||
layers.append(layer)
|
|
||||||
except KeyboardInterrupt:
|
|
||||||
return
|
|
||||||
except Exception as e:
|
|
||||||
self.has_error = e
|
|
||||||
return
|
|
||||||
|
|
||||||
if kind == "color":
|
|
||||||
if np.issubdtype(np.uint8, data.dtype):
|
|
||||||
data = np.multiply(data, 1.0 / 256, dtype=np.float32)
|
|
||||||
elif data.dtype.kind in ["u", "i"]:
|
|
||||||
# Convert the normalized array to float dtype
|
|
||||||
data = data.astype(np.float32)
|
|
||||||
|
|
||||||
min_val = data.min()
|
|
||||||
max_val = data.max()
|
|
||||||
# Avoid division by zero if all values are the same
|
|
||||||
if max_val != min_val:
|
|
||||||
# Normalize the array to the range (0,1)
|
|
||||||
data = (data - min_val) / (max_val - min_val)
|
|
||||||
else:
|
|
||||||
# If all values are the same, the normalized array will be all zeros
|
|
||||||
data = np.zeros_like(data, dtype=np.float32)
|
|
||||||
|
|
||||||
else:
|
|
||||||
data = data.astype(np.float32)
|
|
||||||
|
|
||||||
# Gamma Correct
|
|
||||||
# data = data ** 2.2
|
|
||||||
|
|
||||||
name = self.layer_name or "Color"
|
|
||||||
if data.shape[4] == 1:
|
|
||||||
data = np.repeat(data, repeats=3, axis=4)
|
|
||||||
elif data.shape[4] == 2:
|
|
||||||
d_shape = list(data.shape)
|
|
||||||
d_shape = d_shape[:4] + [1]
|
|
||||||
zore = np.zeros(tuple(d_shape), dtype=np.float32)
|
|
||||||
data = np.concatenate((data, zore), axis=-1)
|
|
||||||
elif data.shape[4] > 3:
|
|
||||||
data = data[:, :, :, :, :3]
|
|
||||||
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
progress_update(context, 0.2, f"Processing {name}...")
|
|
||||||
progress_callback = progress_callback_factory(name, 0.2, 0.7)
|
|
||||||
|
|
||||||
try:
|
|
||||||
layer = Layer(data=data, name=name, kind=kind)
|
|
||||||
|
|
||||||
layer.resize(shape=shape, progress_callback=progress_callback)
|
|
||||||
|
|
||||||
layer.affine = affine
|
|
||||||
|
|
||||||
layers.append(layer)
|
|
||||||
except KeyboardInterrupt:
|
|
||||||
return
|
|
||||||
except Exception as e:
|
|
||||||
self.has_error = e
|
|
||||||
return
|
|
||||||
|
|
||||||
elif kind == "scalar":
|
|
||||||
name = self.layer_name or "Scalar"
|
|
||||||
|
|
||||||
if self.remap:
|
|
||||||
# Convert the normalized array to float dtype
|
|
||||||
data = data.astype(np.float32)
|
|
||||||
|
|
||||||
min_val = data.min()
|
|
||||||
max_val = data.max()
|
|
||||||
# Avoid division by zero if all values are the same
|
|
||||||
if max_val != min_val:
|
|
||||||
# Normalize the array to the range (0,1)
|
|
||||||
data = (data - min_val) / (max_val - min_val)
|
|
||||||
else:
|
|
||||||
# If all values are the same, the normalized array will be all zeros
|
|
||||||
data = np.zeros_like(data, dtype=np.float32)
|
|
||||||
|
|
||||||
if self.split_channel:
|
|
||||||
progress_step = 0.7 / self.channel_count
|
|
||||||
|
|
||||||
for i in range(self.channel_count):
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
name_i = f"{name}_{i+1}"
|
|
||||||
progress = 0.2 + i * progress_step
|
|
||||||
progress_update(context, progress, f"Processing {name_i}...")
|
|
||||||
progress_callback = progress_callback_factory(
|
|
||||||
name_i, progress, progress_step
|
|
||||||
)
|
|
||||||
try:
|
|
||||||
layer = Layer(
|
|
||||||
data=data[:, :, :, :, i : i + 1], name=name_i, kind=kind
|
|
||||||
)
|
|
||||||
|
|
||||||
layer.resize(
|
|
||||||
shape=shape, progress_callback=progress_callback
|
|
||||||
)
|
|
||||||
|
|
||||||
layer.affine = affine
|
|
||||||
|
|
||||||
layers.append(layer)
|
|
||||||
except KeyboardInterrupt:
|
|
||||||
return
|
|
||||||
except Exception as e:
|
|
||||||
self.has_error = e
|
|
||||||
return
|
|
||||||
else:
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
progress_update(context, 0.2, f"Processing {name}...")
|
|
||||||
progress_callback = progress_callback_factory(name, 0.2, 0.7)
|
|
||||||
|
|
||||||
try:
|
|
||||||
layer = Layer(data=data, name=name, kind=kind)
|
|
||||||
|
|
||||||
layer.resize(shape=shape, progress_callback=progress_callback)
|
|
||||||
|
|
||||||
layer.affine = affine
|
|
||||||
|
|
||||||
layers.append(layer)
|
|
||||||
except KeyboardInterrupt:
|
|
||||||
return
|
|
||||||
except Exception as e:
|
|
||||||
self.has_error = e
|
|
||||||
return
|
|
||||||
|
|
||||||
if cancel():
|
|
||||||
return
|
|
||||||
|
|
||||||
self.layers = layers
|
|
||||||
progress_update(context, 0.9, "Creating Layers...")
|
|
||||||
|
|
||||||
self.is_cancelled = False
|
self.is_cancelled = False
|
||||||
self.has_error = None
|
self.has_error = None
|
||||||
|
self.cache_infos = None
|
||||||
|
self.added_ids = None
|
||||||
|
|
||||||
self.thread = threading.Thread(
|
start_worker_process(
|
||||||
target=import_volumetric_data_func,
|
self,
|
||||||
args=(self, context, lambda: self.is_cancelled),
|
"import_layers",
|
||||||
|
{
|
||||||
|
"filepath": self.filepath,
|
||||||
|
"series_id": self.series_id,
|
||||||
|
"cache_dir": str(get_cache_dir() / "layers"),
|
||||||
|
"layer_name": self.layer_name,
|
||||||
|
"orig_shape": list(self.orig_shape),
|
||||||
|
"orig_spacing": list(self.orig_spacing),
|
||||||
|
"bioxel_size": self.bioxel_size,
|
||||||
|
"read_as": self.read_as,
|
||||||
|
"frame_source": self.frame_source,
|
||||||
|
"smooth": self.smooth,
|
||||||
|
"remap": self.remap,
|
||||||
|
"split_channel": self.split_channel,
|
||||||
|
"channel_count": self.channel_count,
|
||||||
|
},
|
||||||
)
|
)
|
||||||
|
|
||||||
self.thread.start()
|
|
||||||
self._timer = context.window_manager.event_timer_add(
|
self._timer = context.window_manager.event_timer_add(
|
||||||
time_step=0.1, window=context.window
|
time_step=0.1, window=context.window
|
||||||
)
|
)
|
||||||
@@ -803,41 +641,49 @@ class ImportDataDialog(bpy.types.Operator):
|
|||||||
|
|
||||||
def modal(self, context, event):
|
def modal(self, context, event):
|
||||||
if event.type == "ESC":
|
if event.type == "ESC":
|
||||||
self.is_cancelled = True
|
cancel_worker_process(self, context)
|
||||||
progress_update(context, 0.0, "Canceling...")
|
|
||||||
return {"PASS_THROUGH"}
|
return {"PASS_THROUGH"}
|
||||||
|
|
||||||
if event.type != "TIMER":
|
if event.type != "TIMER":
|
||||||
return {"PASS_THROUGH"}
|
return {"PASS_THROUGH"}
|
||||||
|
|
||||||
bpy.context.workspace.status_text_set_internal(None)
|
bpy.context.workspace.status_text_set_internal(None)
|
||||||
if self.thread.is_alive():
|
update_worker_progress(self, context)
|
||||||
|
|
||||||
|
if self.process.poll() is None:
|
||||||
return {"PASS_THROUGH"}
|
return {"PASS_THROUGH"}
|
||||||
|
|
||||||
self.thread.join()
|
|
||||||
context.window_manager.event_timer_remove(self._timer)
|
context.window_manager.event_timer_remove(self._timer)
|
||||||
bpy.types.STATUSBAR_HT_header.remove(progress_bar)
|
remove_progress_bar_safe()
|
||||||
progress_update(context, 1.0)
|
progress_update(context, 1.0)
|
||||||
|
|
||||||
if self.is_cancelled:
|
result = read_worker_json(self.result_path)
|
||||||
|
if self.is_cancelled or (result and result.get("cancelled")):
|
||||||
self.report({"WARNING"}, "Canncelled by user.")
|
self.report({"WARNING"}, "Canncelled by user.")
|
||||||
return {"CANCELLED"}
|
return {"CANCELLED"}
|
||||||
|
|
||||||
# Check if thread is cancelled by user
|
if not result:
|
||||||
if self.has_error:
|
self.report({"ERROR"}, f"Import worker failed. See log: {self.log_path}")
|
||||||
raise self.has_error
|
return {"CANCELLED"}
|
||||||
|
|
||||||
# Check if has return
|
if not result.get("ok"):
|
||||||
if self.layers is None:
|
print(result.get("traceback", ""))
|
||||||
|
self.report({"ERROR"}, result.get("error", "Import worker failed."))
|
||||||
|
return {"CANCELLED"}
|
||||||
|
|
||||||
|
self.cache_infos = result.get("cache_infos")
|
||||||
|
self.added_ids = result.get("added_ids")
|
||||||
|
if not self.cache_infos or not self.added_ids:
|
||||||
self.report({"ERROR"}, "Some thing went wrong.")
|
self.report({"ERROR"}, "Some thing went wrong.")
|
||||||
return {"CANCELLED"}
|
return {"CANCELLED"}
|
||||||
|
|
||||||
is_first_import = len(get_layer_caches()) == 0
|
is_first_import = len(get_layer_caches()) == 0
|
||||||
ids = save_layers_to_json(self.layers, cache_dir=get_cache_dir() / "layers")
|
existing_data = get_layer_caches()
|
||||||
|
existing_data.extend(self.cache_infos)
|
||||||
|
set_layer_caches(existing_data)
|
||||||
|
|
||||||
setattr(context.window_manager, "bioxel_layer_library", ids[-1])
|
setattr(context.window_manager, "bioxel_layer_library", self.added_ids[-1])
|
||||||
|
|
||||||
# Change render setting for better result
|
|
||||||
if is_first_import:
|
if is_first_import:
|
||||||
bpy.ops.bioxel.render_setting_preset("EXEC_DEFAULT", preset="balance")
|
bpy.ops.bioxel.render_setting_preset("EXEC_DEFAULT", preset="balance")
|
||||||
|
|
||||||
|
|||||||
263
src/bioxelnodes/operators/io_worker.py
Normal file
263
src/bioxelnodes/operators/io_worker.py
Normal file
@@ -0,0 +1,263 @@
|
|||||||
|
import json
|
||||||
|
import sys
|
||||||
|
import traceback
|
||||||
|
from pathlib import Path
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
import transforms3d
|
||||||
|
|
||||||
|
if __package__:
|
||||||
|
from ..bioxel.layer import Layer
|
||||||
|
from ..bioxel.parse import parse_volumetric_data
|
||||||
|
from ..layer import save_layers_to_cache
|
||||||
|
else:
|
||||||
|
PACKAGE_PARENT = Path(__file__).resolve().parents[2]
|
||||||
|
if str(PACKAGE_PARENT) not in sys.path:
|
||||||
|
sys.path.insert(0, str(PACKAGE_PARENT))
|
||||||
|
|
||||||
|
from bioxelnodes.bioxel.layer import Layer
|
||||||
|
from bioxelnodes.bioxel.parse import parse_volumetric_data
|
||||||
|
from bioxelnodes.layer import save_layers_to_cache
|
||||||
|
|
||||||
|
|
||||||
|
def get_layer_shape(bioxel_size: float, orig_shape: tuple, orig_spacing: tuple):
|
||||||
|
shape = (
|
||||||
|
int(orig_shape[0] / bioxel_size * orig_spacing[0]),
|
||||||
|
int(orig_shape[1] / bioxel_size * orig_spacing[1]),
|
||||||
|
int(orig_shape[2] / bioxel_size * orig_spacing[2]),
|
||||||
|
)
|
||||||
|
|
||||||
|
return (
|
||||||
|
shape[0] if shape[0] > 0 else 1,
|
||||||
|
shape[1] if shape[1] > 0 else 1,
|
||||||
|
shape[2] if shape[2] > 0 else 1,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def write_json(path: Path, data):
|
||||||
|
temp_path = path.with_suffix(path.suffix + ".tmp")
|
||||||
|
temp_path.write_text(json.dumps(data), encoding="utf-8")
|
||||||
|
temp_path.replace(path)
|
||||||
|
|
||||||
|
|
||||||
|
def check_cancel(cancel_path: Path):
|
||||||
|
if cancel_path.exists():
|
||||||
|
raise KeyboardInterrupt("Cancelled by user")
|
||||||
|
|
||||||
|
|
||||||
|
def make_progress_writer(progress_path: Path, cancel_path: Path, scale=1.0, offset=0.0):
|
||||||
|
def progress_callback(factor, text):
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
write_json(
|
||||||
|
progress_path,
|
||||||
|
{
|
||||||
|
"factor": offset + factor * scale,
|
||||||
|
"text": text,
|
||||||
|
},
|
||||||
|
)
|
||||||
|
|
||||||
|
return progress_callback
|
||||||
|
|
||||||
|
|
||||||
|
def progress_callback_factory(progress_path: Path, cancel_path: Path, layer_name, progress, progress_step):
|
||||||
|
def progress_callback(frame, total):
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
sub_progress_step = progress_step / total
|
||||||
|
sub_progress = progress + frame * sub_progress_step
|
||||||
|
text = f"Processing {layer_name} Frame {frame+1}..."
|
||||||
|
write_json(progress_path, {"factor": sub_progress, "text": text})
|
||||||
|
print(text)
|
||||||
|
|
||||||
|
return progress_callback
|
||||||
|
|
||||||
|
|
||||||
|
def read_meta(config, progress_path: Path, cancel_path: Path):
|
||||||
|
progress_callback = make_progress_writer(progress_path, cancel_path)
|
||||||
|
series_id = config["series_id"] if config["series_id"] != "empty" else ""
|
||||||
|
data, meta = parse_volumetric_data(
|
||||||
|
data_file=config["filepath"],
|
||||||
|
series_id=series_id,
|
||||||
|
progress_callback=progress_callback,
|
||||||
|
)
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
return {
|
||||||
|
"meta": {
|
||||||
|
**meta,
|
||||||
|
"spacing": list(meta["spacing"]),
|
||||||
|
"affine": meta["affine"].tolist(),
|
||||||
|
"xyz_shape": list(meta["xyz_shape"]),
|
||||||
|
},
|
||||||
|
"label_count": int(np.max(data)),
|
||||||
|
"dtype": data.dtype.str,
|
||||||
|
"dtype_kind": data.dtype.kind,
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
def build_layers(config, progress_path: Path, cancel_path: Path):
|
||||||
|
write_json(progress_path, {"factor": 0.0, "text": "Parsing Volumetirc Data..."})
|
||||||
|
progress_callback = make_progress_writer(progress_path, cancel_path, scale=0.2)
|
||||||
|
data, meta = parse_volumetric_data(
|
||||||
|
data_file=config["filepath"],
|
||||||
|
series_id=config["series_id"],
|
||||||
|
progress_callback=progress_callback,
|
||||||
|
)
|
||||||
|
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
orig_shape = tuple(config["orig_shape"])
|
||||||
|
orig_spacing = tuple(config["orig_spacing"])
|
||||||
|
shape = get_layer_shape(config["bioxel_size"], orig_shape, orig_spacing)
|
||||||
|
|
||||||
|
mat_scale = transforms3d.zooms.zfdir2aff(config["bioxel_size"])
|
||||||
|
affine = np.dot(meta["affine"], mat_scale)
|
||||||
|
kind = config["read_as"].lower()
|
||||||
|
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
frame_source = config["frame_source"]
|
||||||
|
if frame_source == "-1":
|
||||||
|
data = data[0:1, :, :, :, :]
|
||||||
|
elif frame_source == "0":
|
||||||
|
pass
|
||||||
|
elif frame_source == "1":
|
||||||
|
data = data.transpose(1, 0, 2, 3, 4)
|
||||||
|
shape = (1, shape[1], shape[2])
|
||||||
|
elif frame_source == "2":
|
||||||
|
data = data.transpose(2, 1, 0, 3, 4)
|
||||||
|
shape = (shape[0], 1, shape[2])
|
||||||
|
elif frame_source == "3":
|
||||||
|
data = data.transpose(3, 1, 2, 0, 4)
|
||||||
|
shape = (shape[0], shape[1], 1)
|
||||||
|
else:
|
||||||
|
data = data.transpose(4, 1, 2, 3, 0)
|
||||||
|
|
||||||
|
layers = []
|
||||||
|
if kind == "label":
|
||||||
|
name = config["layer_name"] or "Label"
|
||||||
|
data = data.astype(int)
|
||||||
|
label_count = int(np.max(data))
|
||||||
|
progress_step = 0.7 / label_count
|
||||||
|
|
||||||
|
for i in range(label_count):
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
name_i = f"{name}_{i+1}"
|
||||||
|
progress = 0.2 + i * progress_step
|
||||||
|
write_json(progress_path, {"factor": progress, "text": f"Processing {name_i}..."})
|
||||||
|
progress_callback = progress_callback_factory(
|
||||||
|
progress_path, cancel_path, name_i, progress, progress_step
|
||||||
|
)
|
||||||
|
label_data = data == np.full_like(data, i + 1)
|
||||||
|
layer = Layer(data=label_data, name=name_i, kind=kind)
|
||||||
|
layer.resize(
|
||||||
|
shape=shape,
|
||||||
|
smooth=config["smooth"],
|
||||||
|
progress_callback=progress_callback,
|
||||||
|
)
|
||||||
|
layer.affine = affine
|
||||||
|
layers.append(layer)
|
||||||
|
|
||||||
|
if kind == "color":
|
||||||
|
if np.issubdtype(np.uint8, data.dtype):
|
||||||
|
data = np.multiply(data, 1.0 / 256, dtype=np.float32)
|
||||||
|
elif data.dtype.kind in ["u", "i"]:
|
||||||
|
data = data.astype(np.float32)
|
||||||
|
min_val = data.min()
|
||||||
|
max_val = data.max()
|
||||||
|
if max_val != min_val:
|
||||||
|
data = (data - min_val) / (max_val - min_val)
|
||||||
|
else:
|
||||||
|
data = np.zeros_like(data, dtype=np.float32)
|
||||||
|
else:
|
||||||
|
data = data.astype(np.float32)
|
||||||
|
|
||||||
|
name = config["layer_name"] or "Color"
|
||||||
|
if data.shape[4] == 1:
|
||||||
|
data = np.repeat(data, repeats=3, axis=4)
|
||||||
|
elif data.shape[4] == 2:
|
||||||
|
d_shape = list(data.shape)
|
||||||
|
d_shape = d_shape[:4] + [1]
|
||||||
|
zore = np.zeros(tuple(d_shape), dtype=np.float32)
|
||||||
|
data = np.concatenate((data, zore), axis=-1)
|
||||||
|
elif data.shape[4] > 3:
|
||||||
|
data = data[:, :, :, :, :3]
|
||||||
|
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
write_json(progress_path, {"factor": 0.2, "text": f"Processing {name}..."})
|
||||||
|
progress_callback = progress_callback_factory(progress_path, cancel_path, name, 0.2, 0.7)
|
||||||
|
layer = Layer(data=data, name=name, kind=kind)
|
||||||
|
layer.resize(shape=shape, progress_callback=progress_callback)
|
||||||
|
layer.affine = affine
|
||||||
|
layers.append(layer)
|
||||||
|
|
||||||
|
elif kind == "scalar":
|
||||||
|
name = config["layer_name"] or "Scalar"
|
||||||
|
|
||||||
|
if config["remap"]:
|
||||||
|
data = data.astype(np.float32)
|
||||||
|
min_val = data.min()
|
||||||
|
max_val = data.max()
|
||||||
|
if max_val != min_val:
|
||||||
|
data = (data - min_val) / (max_val - min_val)
|
||||||
|
else:
|
||||||
|
data = np.zeros_like(data, dtype=np.float32)
|
||||||
|
|
||||||
|
if config["split_channel"]:
|
||||||
|
progress_step = 0.7 / config["channel_count"]
|
||||||
|
|
||||||
|
for i in range(config["channel_count"]):
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
name_i = f"{name}_{i+1}"
|
||||||
|
progress = 0.2 + i * progress_step
|
||||||
|
write_json(progress_path, {"factor": progress, "text": f"Processing {name_i}..."})
|
||||||
|
progress_callback = progress_callback_factory(
|
||||||
|
progress_path, cancel_path, name_i, progress, progress_step
|
||||||
|
)
|
||||||
|
layer = Layer(data=data[:, :, :, :, i : i + 1], name=name_i, kind=kind)
|
||||||
|
layer.resize(shape=shape, progress_callback=progress_callback)
|
||||||
|
layer.affine = affine
|
||||||
|
layers.append(layer)
|
||||||
|
else:
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
write_json(progress_path, {"factor": 0.2, "text": f"Processing {name}..."})
|
||||||
|
progress_callback = progress_callback_factory(progress_path, cancel_path, name, 0.2, 0.7)
|
||||||
|
layer = Layer(data=data, name=name, kind=kind)
|
||||||
|
layer.resize(shape=shape, progress_callback=progress_callback)
|
||||||
|
layer.affine = affine
|
||||||
|
layers.append(layer)
|
||||||
|
|
||||||
|
check_cancel(cancel_path)
|
||||||
|
write_json(progress_path, {"factor": 0.9, "text": "Creating Layers..."})
|
||||||
|
cache_infos = save_layers_to_cache(layers, config["cache_dir"])
|
||||||
|
return {"cache_infos": cache_infos, "added_ids": [item["id"] for item in cache_infos]}
|
||||||
|
|
||||||
|
|
||||||
|
def main():
|
||||||
|
config_path = Path(sys.argv[-1])
|
||||||
|
config = json.loads(config_path.read_text(encoding="utf-8"))
|
||||||
|
progress_path = Path(config["progress_path"])
|
||||||
|
result_path = Path(config["result_path"])
|
||||||
|
cancel_path = Path(config["cancel_path"])
|
||||||
|
|
||||||
|
try:
|
||||||
|
if config["command"] == "read_meta":
|
||||||
|
result = read_meta(config, progress_path, cancel_path)
|
||||||
|
elif config["command"] == "import_layers":
|
||||||
|
result = build_layers(config, progress_path, cancel_path)
|
||||||
|
else:
|
||||||
|
raise ValueError(f"Unknown command: {config['command']}")
|
||||||
|
|
||||||
|
write_json(result_path, {"ok": True, **result})
|
||||||
|
write_json(progress_path, {"factor": 1.0, "text": ""})
|
||||||
|
except KeyboardInterrupt:
|
||||||
|
write_json(result_path, {"ok": False, "cancelled": True})
|
||||||
|
except Exception as e:
|
||||||
|
write_json(
|
||||||
|
result_path,
|
||||||
|
{
|
||||||
|
"ok": False,
|
||||||
|
"error": str(e),
|
||||||
|
"traceback": traceback.format_exc(),
|
||||||
|
},
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
if __name__ == "__main__":
|
||||||
|
main()
|
||||||
@@ -5,6 +5,7 @@ import bpy
|
|||||||
from pathlib import Path
|
from pathlib import Path
|
||||||
import shutil
|
import shutil
|
||||||
|
|
||||||
|
from ..asset_library import add_bioxel_asset_library
|
||||||
from ..constants import LATEST_NODE_LIB_PATH
|
from ..constants import LATEST_NODE_LIB_PATH
|
||||||
from ..utils import (
|
from ..utils import (
|
||||||
get_all_layer_objs,
|
get_all_layer_objs,
|
||||||
@@ -120,6 +121,27 @@ class Help(bpy.types.Operator):
|
|||||||
return {"FINISHED"}
|
return {"FINISHED"}
|
||||||
|
|
||||||
|
|
||||||
|
class AddAssetLibrary(bpy.types.Operator):
|
||||||
|
bl_idname = "bioxel.add_asset_library"
|
||||||
|
bl_label = "Add Nodes Library"
|
||||||
|
bl_description = "Add the bundled O Bioxel asset library"
|
||||||
|
|
||||||
|
def execute(self, context):
|
||||||
|
try:
|
||||||
|
add_bioxel_asset_library()
|
||||||
|
except FileNotFoundError as e:
|
||||||
|
self.report({"ERROR"}, str(e))
|
||||||
|
return {"CANCELLED"}
|
||||||
|
|
||||||
|
for window in context.window_manager.windows:
|
||||||
|
for area in window.screen.areas:
|
||||||
|
if area.type == "NODE_EDITOR":
|
||||||
|
area.tag_redraw()
|
||||||
|
|
||||||
|
self.report({"INFO"}, "O Bioxel asset library is ready.")
|
||||||
|
return {"FINISHED"}
|
||||||
|
|
||||||
|
|
||||||
# 定义虚无化切换操作
|
# 定义虚无化切换操作
|
||||||
class TogglePhantom(bpy.types.Operator):
|
class TogglePhantom(bpy.types.Operator):
|
||||||
"""Toggle object phantom state (ray invisible, no shadows, semi-transparent wireframe)"""
|
"""Toggle object phantom state (ray invisible, no shadows, semi-transparent wireframe)"""
|
||||||
|
|||||||
@@ -1,11 +1,12 @@
|
|||||||
from pathlib import Path
|
from pathlib import Path
|
||||||
import bpy
|
import bpy
|
||||||
|
|
||||||
|
from .asset_library import has_bioxel_asset_library
|
||||||
from .node import get_layer_nodes, get_main_node_group
|
from .node import get_layer_nodes, get_main_node_group
|
||||||
from .utils import load_icon
|
from .utils import load_icon
|
||||||
from .layer import get_layer_caches
|
from .layer import get_layer_caches
|
||||||
from .operators.io import ImportAsColor, ImportAsLabel, ImportAsScalar, ImportData
|
from .operators.io import ImportAsColor, ImportAsLabel, ImportAsScalar, ImportData
|
||||||
from .operators.misc import Help, RenderSettingPreset
|
from .operators.misc import AddAssetLibrary, Help, RenderSettingPreset
|
||||||
from .operators.layer import (
|
from .operators.layer import (
|
||||||
AddLayerNode,
|
AddLayerNode,
|
||||||
DeleteLayer,
|
DeleteLayer,
|
||||||
@@ -54,22 +55,38 @@ class BioxelPanelBase:
|
|||||||
bl_region_type = "UI"
|
bl_region_type = "UI"
|
||||||
bl_context = "geometry_node"
|
bl_context = "geometry_node"
|
||||||
bl_category = "Bioxel Nodes"
|
bl_category = "Bioxel Nodes"
|
||||||
|
requires_asset_library = True
|
||||||
# try to make Bioxel panels order early (may be respected by Blender)
|
# try to make Bioxel panels order early (may be respected by Blender)
|
||||||
|
|
||||||
@classmethod
|
@classmethod
|
||||||
def poll(cls, context):
|
def poll(cls, context):
|
||||||
node_group = get_main_node_group(context)
|
node_group = get_main_node_group(context)
|
||||||
return node_group is not None
|
if node_group is None:
|
||||||
|
return False
|
||||||
|
|
||||||
|
if not getattr(cls, "requires_asset_library", True):
|
||||||
|
return True
|
||||||
|
|
||||||
|
return has_bioxel_asset_library()
|
||||||
|
|
||||||
|
|
||||||
class HeaderPanel(bpy.types.Panel, BioxelPanelBase):
|
class HeaderPanel(bpy.types.Panel, BioxelPanelBase):
|
||||||
bl_label = "Bioxel Nodes"
|
bl_label = "Bioxel Nodes"
|
||||||
bl_idname = "BIOXEL_PT_header_panel"
|
bl_idname = "BIOXEL_PT_header_panel"
|
||||||
bl_order = 0
|
bl_order = 0
|
||||||
|
requires_asset_library = False
|
||||||
|
|
||||||
def draw(self, context):
|
def draw(self, context):
|
||||||
layout = self.layout
|
layout = self.layout
|
||||||
|
|
||||||
|
if not has_bioxel_asset_library():
|
||||||
|
layout.operator(
|
||||||
|
AddAssetLibrary.bl_idname,
|
||||||
|
text="Add Nodes Library",
|
||||||
|
icon="ASSET_MANAGER",
|
||||||
|
)
|
||||||
|
return
|
||||||
|
|
||||||
layout.operator(
|
layout.operator(
|
||||||
Help.bl_idname, text="Help", icon=Help.bl_icon # 复用原操作的图标定义
|
Help.bl_idname, text="Help", icon=Help.bl_icon # 复用原操作的图标定义
|
||||||
)
|
)
|
||||||
|
|||||||
25
uv.lock
generated
25
uv.lock
generated
@@ -25,13 +25,14 @@ wheels = [
|
|||||||
|
|
||||||
[[package]]
|
[[package]]
|
||||||
name = "bioxelnodes"
|
name = "bioxelnodes"
|
||||||
version = "1.0.9"
|
version = "2.0.0"
|
||||||
source = { editable = "." }
|
source = { editable = "." }
|
||||||
dependencies = [
|
dependencies = [
|
||||||
{ name = "h5py" },
|
{ name = "h5py" },
|
||||||
{ name = "matplotlib" },
|
{ name = "matplotlib" },
|
||||||
{ name = "mrcfile" },
|
{ name = "mrcfile" },
|
||||||
{ name = "pyometiff" },
|
{ name = "pyometiff" },
|
||||||
|
{ name = "scipy" },
|
||||||
{ name = "simpleitk" },
|
{ name = "simpleitk" },
|
||||||
{ name = "transforms3d" },
|
{ name = "transforms3d" },
|
||||||
]
|
]
|
||||||
@@ -59,6 +60,7 @@ requires-dist = [
|
|||||||
{ name = "matplotlib", specifier = "==3.10.7" },
|
{ name = "matplotlib", specifier = "==3.10.7" },
|
||||||
{ name = "mrcfile", specifier = "==1.5.1" },
|
{ name = "mrcfile", specifier = "==1.5.1" },
|
||||||
{ name = "pyometiff", specifier = "==1.0.0" },
|
{ name = "pyometiff", specifier = "==1.0.0" },
|
||||||
|
{ name = "scipy", specifier = "==1.17.1" },
|
||||||
{ name = "simpleitk", specifier = "==2.3.1" },
|
{ name = "simpleitk", specifier = "==2.3.1" },
|
||||||
{ name = "transforms3d", specifier = "==0.4.2" },
|
{ name = "transforms3d", specifier = "==0.4.2" },
|
||||||
]
|
]
|
||||||
@@ -945,6 +947,27 @@ wheels = [
|
|||||||
{ url = "https://files.pythonhosted.org/packages/f9/9b/335f9764261e915ed497fcdeb11df5dfd6f7bf257d4a6a2a686d80da4d54/requests-2.32.3-py3-none-any.whl", hash = "sha256:70761cfe03c773ceb22aa2f671b4757976145175cdfca038c02654d061d6dcc6", size = 64928, upload-time = "2024-05-29T15:37:47.027Z" },
|
{ url = "https://files.pythonhosted.org/packages/f9/9b/335f9764261e915ed497fcdeb11df5dfd6f7bf257d4a6a2a686d80da4d54/requests-2.32.3-py3-none-any.whl", hash = "sha256:70761cfe03c773ceb22aa2f671b4757976145175cdfca038c02654d061d6dcc6", size = 64928, upload-time = "2024-05-29T15:37:47.027Z" },
|
||||||
]
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "scipy"
|
||||||
|
version = "1.17.1"
|
||||||
|
source = { registry = "https://pypi.org/simple" }
|
||||||
|
dependencies = [
|
||||||
|
{ name = "numpy" },
|
||||||
|
]
|
||||||
|
sdist = { url = "https://files.pythonhosted.org/packages/7a/97/5a3609c4f8d58b039179648e62dd220f89864f56f7357f5d4f45c29eb2cc/scipy-1.17.1.tar.gz", hash = "sha256:95d8e012d8cb8816c226aef832200b1d45109ed4464303e997c5b13122b297c0", size = 30573822, upload-time = "2026-02-23T00:26:24.851Z" }
|
||||||
|
wheels = [
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/df/75/b4ce781849931fef6fd529afa6b63711d5a733065722d0c3e2724af9e40a/scipy-1.17.1-cp311-cp311-macosx_10_14_x86_64.whl", hash = "sha256:1f95b894f13729334fb990162e911c9e5dc1ab390c58aa6cbecb389c5b5e28ec", size = 31613675, upload-time = "2026-02-23T00:16:00.13Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/f7/58/bccc2861b305abdd1b8663d6130c0b3d7cc22e8d86663edbc8401bfd40d4/scipy-1.17.1-cp311-cp311-macosx_12_0_arm64.whl", hash = "sha256:e18f12c6b0bc5a592ed23d3f7b891f68fd7f8241d69b7883769eb5d5dfb52696", size = 28162057, upload-time = "2026-02-23T00:16:09.456Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/6d/ee/18146b7757ed4976276b9c9819108adbc73c5aad636e5353e20746b73069/scipy-1.17.1-cp311-cp311-macosx_14_0_arm64.whl", hash = "sha256:a3472cfbca0a54177d0faa68f697d8ba4c80bbdc19908c3465556d9f7efce9ee", size = 20334032, upload-time = "2026-02-23T00:16:17.358Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/ec/e6/cef1cf3557f0c54954198554a10016b6a03b2ec9e22a4e1df734936bd99c/scipy-1.17.1-cp311-cp311-macosx_14_0_x86_64.whl", hash = "sha256:766e0dc5a616d026a3a1cffa379af959671729083882f50307e18175797b3dfd", size = 22709533, upload-time = "2026-02-23T00:16:25.791Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/4d/60/8804678875fc59362b0fb759ab3ecce1f09c10a735680318ac30da8cd76b/scipy-1.17.1-cp311-cp311-manylinux_2_27_aarch64.manylinux_2_28_aarch64.whl", hash = "sha256:744b2bf3640d907b79f3fd7874efe432d1cf171ee721243e350f55234b4cec4c", size = 33062057, upload-time = "2026-02-23T00:16:36.931Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/09/7d/af933f0f6e0767995b4e2d705a0665e454d1c19402aa7e895de3951ebb04/scipy-1.17.1-cp311-cp311-manylinux_2_27_x86_64.manylinux_2_28_x86_64.whl", hash = "sha256:43af8d1f3bea642559019edfe64e9b11192a8978efbd1539d7bc2aaa23d92de4", size = 35349300, upload-time = "2026-02-23T00:16:49.108Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/b4/3d/7ccbbdcbb54c8fdc20d3b6930137c782a163fa626f0aef920349873421ba/scipy-1.17.1-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:cd96a1898c0a47be4520327e01f874acfd61fb48a9420f8aa9f6483412ffa444", size = 35127333, upload-time = "2026-02-23T00:17:01.293Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/e8/19/f926cb11c42b15ba08e3a71e376d816ac08614f769b4f47e06c3580c836a/scipy-1.17.1-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:4eb6c25dd62ee8d5edf68a8e1c171dd71c292fdae95d8aeb3dd7d7de4c364082", size = 37741314, upload-time = "2026-02-23T00:17:12.576Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/95/da/0d1df507cf574b3f224ccc3d45244c9a1d732c81dcb26b1e8a766ae271a8/scipy-1.17.1-cp311-cp311-win_amd64.whl", hash = "sha256:d30e57c72013c2a4fe441c2fcb8e77b14e152ad48b5464858e07e2ad9fbfceff", size = 36607512, upload-time = "2026-02-23T00:17:23.424Z" },
|
||||||
|
{ url = "https://files.pythonhosted.org/packages/68/7f/bdd79ceaad24b671543ffe0ef61ed8e659440eb683b66f033454dcee90eb/scipy-1.17.1-cp311-cp311-win_arm64.whl", hash = "sha256:9ecb4efb1cd6e8c4afea0daa91a87fbddbce1b99d2895d151596716c0b2e859d", size = 24599248, upload-time = "2026-02-23T00:17:34.561Z" },
|
||||||
|
]
|
||||||
|
|
||||||
[[package]]
|
[[package]]
|
||||||
name = "setuptools"
|
name = "setuptools"
|
||||||
version = "72.1.0"
|
version = "72.1.0"
|
||||||
|
|||||||
Reference in New Issue
Block a user